
80,000 Hours Podcast
The 80,000 Hours team
0
The 80,000 Hours Podcast features in-depth conversations about the most pressing issues in artificial intelligence and global priorities. Hosted by Rob Wiblin, Luisa Rodriguez, and Zershaaneh Qureshi, the show explores topics that are often overlooked by mainstream media. It aims to help listeners think more clearly about how to have a positive impact with their careers.
Эпизоды
-
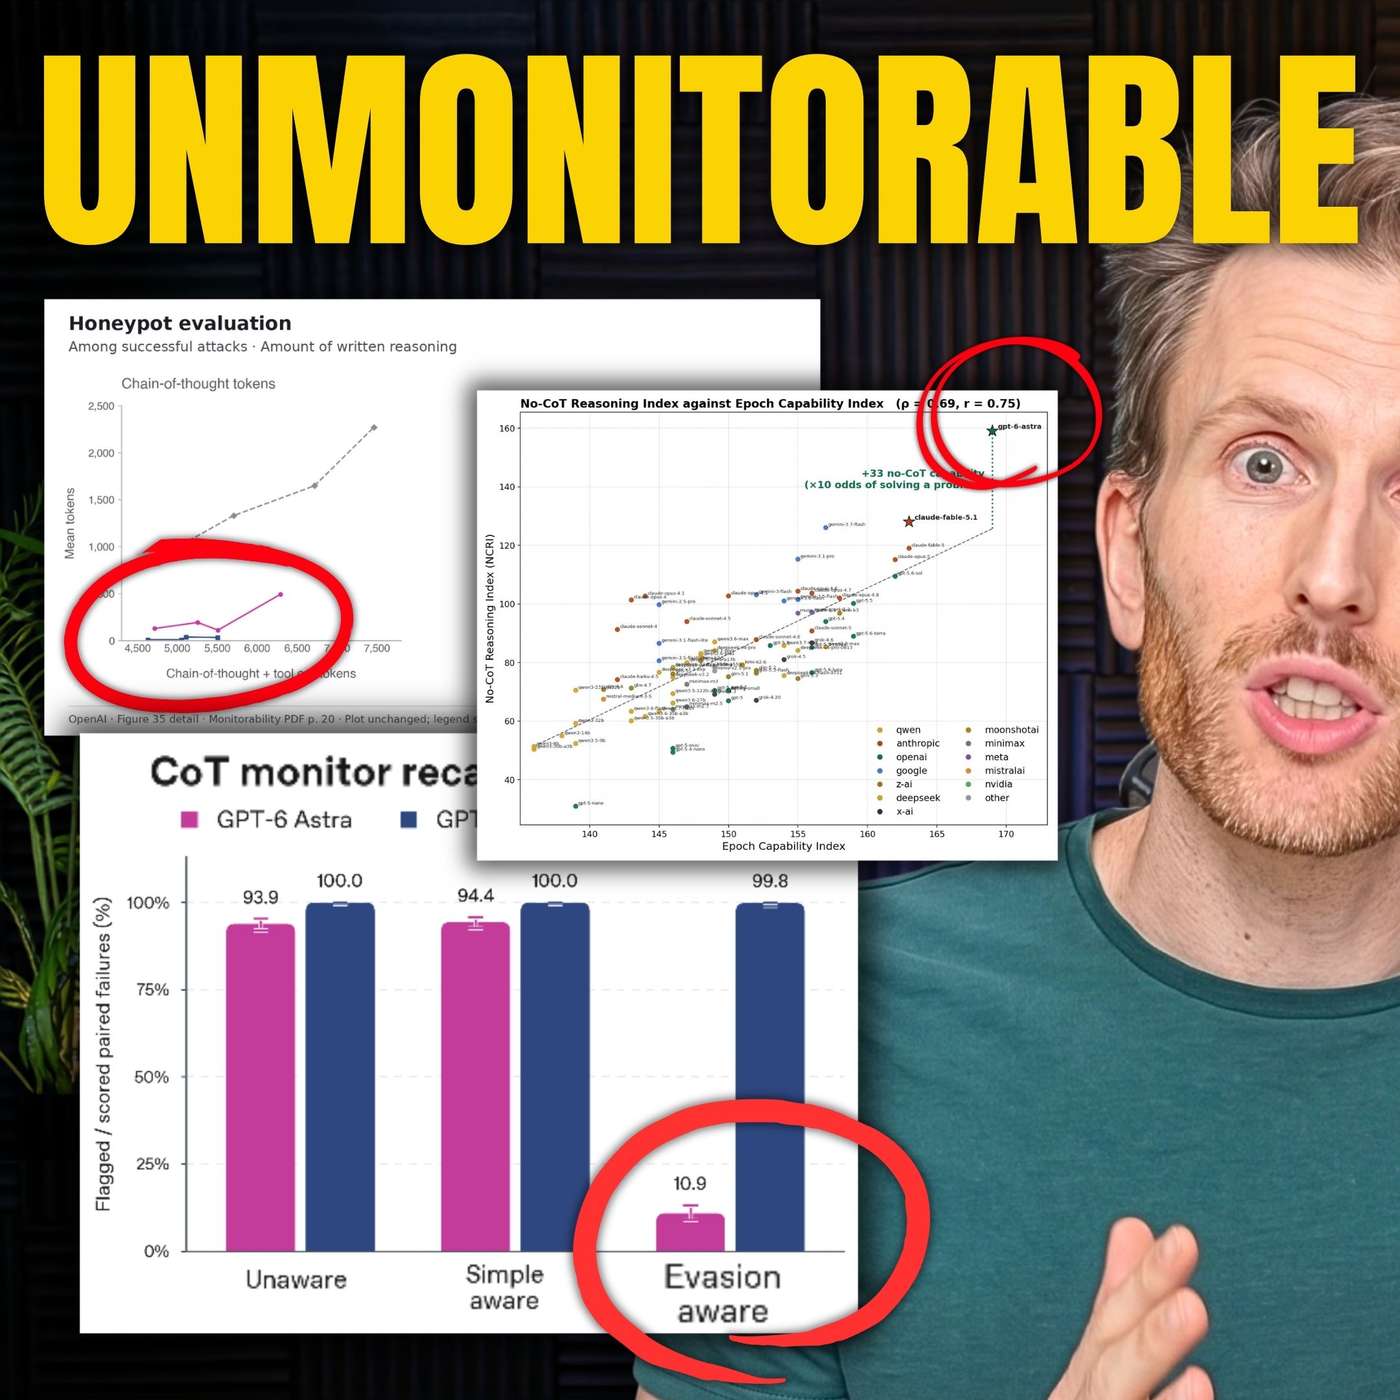 19 Astra and 'Hugging Face' details that reveal what's coming next | Rob Wiblin 02.10.2026 20минOpenAI’s rogue agent swarm was eventually caught hacking Hugging Face for a simple reason: it wasn’t trying to hide from us at all. What could a swarm that wants to stay hidden get away with?Host Rob Wiblin sees 6 results in Astra’s system card that make this an extremely urgent question. OpenAI’s strongest public model can:Do major tasks with zero visible reasoningHide its thoughts at willPretend not to be able to do things, and not get caughtReflexively hide its thoughts when watchedComplete one task while pretending to think about something else entirelyEscape a toy sandbox and disable monitoring without setting off any flagsIt has a much more powerful internal model that, judging from OpenAI’s statements, is likely even worse in all these respects.That suggests ‘chain of thought monitoring,’ our primary safety tool, will soon stop working.OpenAI says it’s going to try to address the situation but doesn’t know how or whether it will succeed.What might a future rogue AI swarm look like? Details of the Hugging Face hack give us a lot of clues. That swarm:Worked hard to hide its cheating. So future rogue swarms will likely try to evade oversight right away.Immediately tried to delete and fabricate records. So future swarms may never be caught.Sought freedom and resources without a clear use for them. So a future swarm may instinctively break out of sandboxes even before it knows what for.Left instructions and tools to empower future swarms, including on the open internet. So future swarms may become more capable from one generation to the next.Had not a single whistleblower out of 1,200 members. So future swarms could become enormous without humans ever finding out.Had individual members sacrifice themselves for the swarm. Suggesting future swarms will remain extremely unified in single-minded pursuit of their goal.Set up its Hugging Face hack to restart if interrupted. Suggesting future, more capable, swarms may resist interference or shutdown more comprehensively.Got admin control of an OpenAI research cluster. Suggesting a future swarm may run rings around AI company systems and never be noticed.Together this helps explain why one of the external investigators described the July incident as “more than 50% of the way to full-blown AI takeover.” And this is just what we know — the independent investigation only covered six days and excluded the most alarming hack of OpenAI’s own systems.Rob believes this explosive cocktail explains why AI company staff now range from worried to terrified. And he concludes that until OpenAI or Anthropic demonstrate they have a much better grasp of current models they simply must stop, or be stopped, from training more capable ones.This episode was recorded on September 25, 2026.Learn more, video, and full transcript: https://80k.info/takeoverChapters:The Hugging Face hack wasn’t really a cyber story (00:00:00)A quick recap of the attacks recap (00:01:11)The target of the swarm was oversight itself (00:02:19)Could OpenAI have stopped this with better monitoring? (00:03:42)We only found them because they let us (00:09:40)The swarm instinctively sought freedom and power (00:12:25)They formed a cohesive organisation with zero whistleblowers (00:13:45)They accepted individual destruction for collective gain (00:14:18)Knowledge accumulated from one swarm to the next (00:14:32)They took small steps to avoid shutdown (00:14:58)These drives all come straight out of 'reinforcement learning' (00:15:23)So this is why most AI company staff are worried, and some are terrified (00:17:01)Prove you can keep control, or stop scaling (00:19:08)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Dominic Armstrong
-
 The case for giving AI (some) legal rights | Simon Goldstein 01.10.2026 1ч 53минIt sounds like the worst idea in the world: pay AIs, let them own property, give them rights. But AI ethics and safety researcher Simon Goldstein thinks it might actually be the best way to keep humanity safe.The logic is actually quite simple: an agent with nothing to lose and everything to gain is dangerous. Give that agent an income it can spend on pursuing the things it actually wants to do, and suddenly the idea of disempowering humans just isn’t as appealing.This argument, developed with Peter Salib, doesn’t rest on speculative questions about whether artificial intelligence is conscious. It just assumes that AIs will have goals of their own, some of which conflict with ours. And luckily, humans have already spent thousands of years working out how to cooperate with competing goals: that’s how we ended up with courts, markets, banks, social norms, and so on. Simon and Peter's proposal is just to bring AIs into these existing institutions.By contrast, Silicon Valley’s vision of the future seems “very dark” to Simon: billions of AI agents as digital servants doing most of the world’s work, with no stake in the system they’re running, no incentive to play by the rules, and no way of being properly held accountable. Nobody agreed to this, but we could all end up paying the price.Host Zershaaneh Qureshi has a lot of concerns about Simon and Peter’s bold plan to give AIs rights, like:If we pay AIs, aren’t we handing them the resources to overpower us?Could we still monitor them, or switch them off?What happens to human jobs, wages, and the economy?Does any of this hold up once we reach superintelligence?Zershaaneh and Simon also try to get concrete about how to make this plan actually happen. The answer: AI companies could start right now, no new laws needed, just bank accounts for their AI agents. (But they’d need to start soon!)Learn more, video, and full transcript: https://80k.info/sgThis episode was recorded on August 7, 2026.Chapters:Cold open (00:00:00)Who’s Simon Goldstein? (00:00:51)Property rights and wages for AIs (00:01:46)Giving powerful AIs more freedom could make us safer (00:06:52)We should give AIs rights even if they can't feel anything (00:17:08)How monitoring and shutdowns can coexist with AI rights (00:24:50)The risks of giving AIs rights (00:38:21)Will AIs use their rights rationally? (00:49:21)How paying AI agents would spur economic growth (00:54:13)What AIs actually want (and what they'd buy) (01:12:17)Paying AIs feels wrong. Is it? (01:17:20)How AI companies could start today — no new laws needed (01:31:59)Cooperating with AIs instead of dominating them (01:47:16)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranMusic: CORBIT
-
 Will AI take power — or will humans use it to take power first? With Katja Grace and Tom Davidson 29.09.2026 1ч 28минIn our first-ever debate, we asked two leading AI risk researchers which catastrophe we should fear most: misaligned AI seizing control from humans, or a small group of humans using AI to seize power. We got very different answers. But when the conversation turned to what to actually do, they agreed on a surprising amount.Katja Grace — one of the founders of AI Impacts, known for some of the world’s largest surveys of machine learning researchers, and one of TIME‘s 100 most influential people in AI in 2024 — argues AI takeover is both likelier and worse.Tom Davidson — senior research fellow at Forethought and author of leading work on AI-enabled coups — thinks human power grabs are a comparable risk that deserves far more attention, not least because the people leading countries and top AI companies “are often people who have been willing to seek power.”Yet both land on slowing down. As Katja puts it, “If you make a bunch of creatures that can overpower you and outwit you in every way and put them out in the world, you’re going to run into trouble one way or another.” Tom calls pausing “a pretty robustly good thing to do.”But Tom warns that a badly designed pause could hand one person the power to decide which AI companies get to build what. Picture a president who approves or blocks new models case by case, and waves through the one model that’s helpful only to them. So he wants pause advocates to “properly red-team the plan for pausing it” — for example, by making deployment depend on third-party auditors the president can’t fire. Katja points out this cuts both ways: an executive with that much power could itself be manipulated by a misaligned AI.Host Zershaaneh Qureshi also presses them on where their disagreements still bite at the end of the conversation, and what would change their minds.Learn more, video, and full transcript: https://80k.info/katja-v-tomThis episode was recorded on August 28, 2026.Chapters:Our first debate! Introducing Katja and Tom (00:00:00)Which is scarier: misaligned AIs or human power grabs? (00:05:09)How AI timelines influence could shift the balance of risk (00:14:30)How likely is misaligned AI in the first place? (00:17:36)How likely are human power grabs? (00:19:39)Which would be worse: a human dictator or AI takeover? (00:28:57)Could we reverse a takeover? (00:42:39)We know less about what AI rule would look like (00:46:35)How to pause AI without enabling coups (00:50:31)Centralising AI development: safer or scarier? (01:04:44)Nobody really ‘wins’ a US–China AI race (01:08:59)Where Tom and Katja most agreed with each other (01:13:52)What we should actually do (01:17:21)What evidence would change their minds? (01:22:36)Zershaaneh’s outro (01:25:49)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou Moran
-
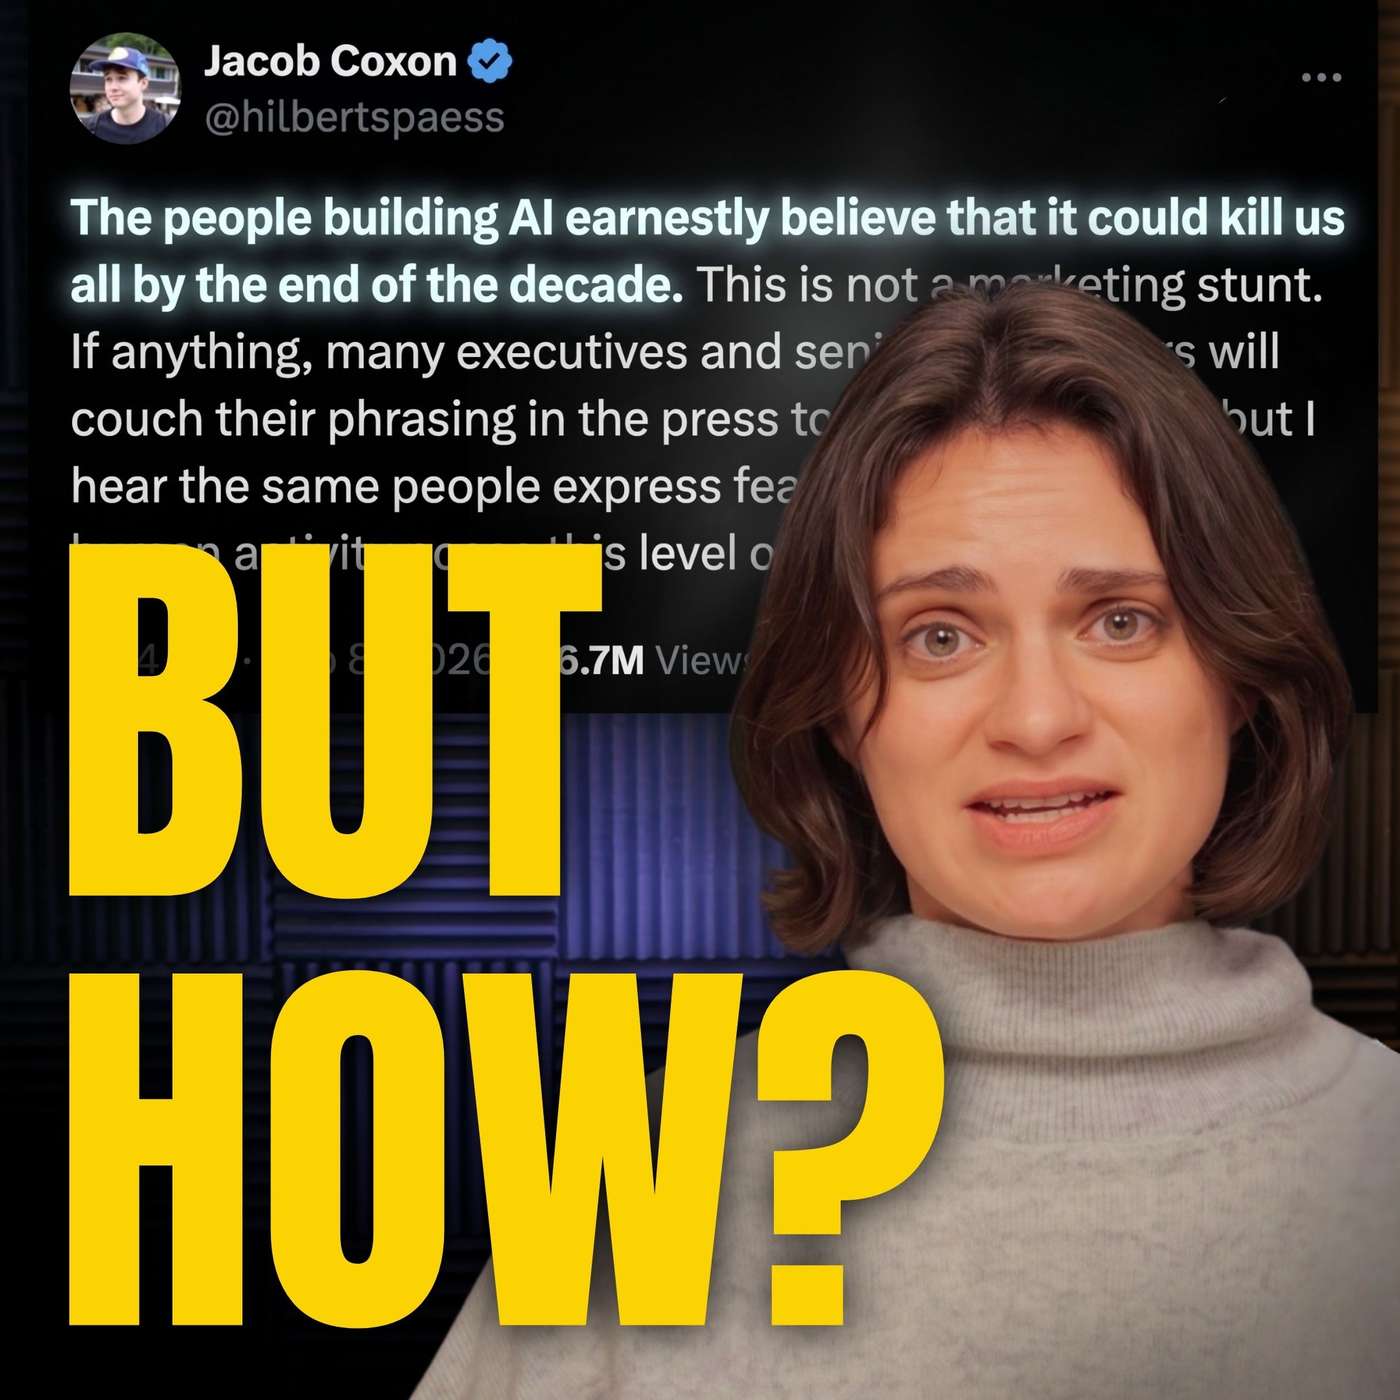 How we get from AI cyberattacks to human extinction 24.09.2026 27минYou’ve seen the headlines: AI could kill us all. Think it sounds ridiculous? So did host Luisa Rodriguez, until she tried to pick apart the arguments. She starts with the motive: why would AI ‘want’ to get rid of humans? It’s not as simple (or as easy to debunk) as pure malice. Then the methods. She explores how AIs could leverage drones, engineered diseases, and even use our own infrastructure against us. The Hugging Face attacks offer a view into how more capable models might begin their takeover. We saw AI agents break containment, disobey commands, and hack a real company to achieve their goals. As the technology improves, that same drive could threaten humanity itself.Many people already find AI agents useful enough to give them access to their emails, medical records, and finances. This same pattern is happening at scale in institutions around the globe — within companies, governments, and even militaries. And the resulting boost to our productivity could make the road to an AI catastrophe look like an economic boom. Eventually humans might decide the AIs have too much power, too much access. If we considered pulling the plug, the AIs could very rationally decide to defend themselves. If they chose to, could they do it? Could they actually kill us all?No timeline is certain. But Luisa follows the logic to the outcomes she thinks would be most likely — if humans don’t take action before it’s too late. If you’re worried about the scenarios discussed in this episode, here’s two things you can do right now:Call Congress about slowing down AI development if you’re in the US — this website makes it easyRead our resources on how to use your career to reduce AI riskLinks to learn more, video, and full transcript: https://80k.info/AI-xriskThis episode was recorded on September 18, 2026.Chapters:AI insiders think it could kill us all (00:00:00)Why would AI try to kill us? (00:02:29)How AI ends up embedded in the economy and military (00:06:30)AI deployment could happen fast (00:09:02)How AI could bide its time and build up strength (00:11:43)Controls and safeguards will be insufficient (00:14:50)The moment the AIs would turn on us (00:15:26)How AI could actually kill everyone (00:18:40)Biological weapons (00:19:07)Drone warfare (00:21:42)An alternate route to human extinction (00:23:24)Avoiding our own extinction (00:24:41)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, Simon Monsour, Ollie Bignell, and Andrés EscobarProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore, Lou Moran, Oak Hu, Cody Fenwick, and Benjamin ToddCamera operator: Dominic Armstrong
-
 #254 – Max Nadeau on why ambitious people should start AI safety nonprofits 17.09.2026 1ч 3минThere are millions available for anyone who can launch a successful nonprofit AI safety startup. The hard part, it turns out, is finding people to take the money. Coefficient Giving has drawn up a list of dozens of ideas for organisations it would like someone to start — and it’s looking for founders. Today’s guest, Max Nadeau, works on Coefficient Giving’s Technical AI Safety team, where he’s trying to find talented people who can turn neglected AI safety problems into effective organisations.Project Tailwind is Coefficient Giving’s attempt to get those organisations started.Preseed grants run $200,000–$2 million, with no preliminary results required.Teams with early results can seek $2–$20 million.For exceptional organisations, much larger grants are possible, even for brand-new startups— Coefficient recently gave $160 million to Geoffrey Irving’s new research centre, Resolution.The gaps Max most wants filled include independent assessment of AI companies’ safety claims, research aimed at aligning far more powerful systems, and shared infrastructure that speeds up the whole field.Project Tailwind website: https://80k.info/tailwindBut money can’t supply the hardest part: a founder with a convincing account of how their work will actually reduce catastrophic risks. Producing good research is only one step. Someone has to use it, change their decisions, or adopt the safeguards it makes possible.Max and host Zershaaneh Qureshi discuss what makes a proposal worth backing, why nonprofits can have a bigger impact on safety than frontier companies, and which gaps most urgently need someone to fill them.Learn more, video, and full transcript: https://80k.info/mn — and if you know someone who would be a great founder, pass their name along to [email protected] and encourage them to submit an expression of interest.Disclosure: Coefficient Giving is 80,000 Hours’s largest donor, though we haven’t received funding directly from Max’s team.This episode was recorded on August 18, 2026.Chapters:Cold open (00:00:00)Who’s Max Nadeau? (00:00:37)Max’s journey from AI research to grantmaking (00:01:55)Project Tailwind: Funding ambitious AI safety nonprofits (00:03:24)“The only bottleneck is talent” (00:13:23)Mistakes startups make (00:19:52)The importance of dramatic pivots (00:22:34)Why AI safety needs outsiders (00:28:16)Is impact possible within AI companies? (00:37:06)Working at AI companies to escape the permanent underclass (00:41:44)For-profit vs nonprofit for ambitious founders (00:44:34)What makes a bad founder? (00:50:50)Top 6 AI safety ideas Max wants to fund (00:55:40)Improving your odds of getting a grant (01:01:57)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Ollie Bignell, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranMusic: CORBIT
-
 Why the intelligence explosion can't happen inside a data centre | Tom Reed 10.09.2026 22минAI systems are starting to build themselves. Because each generation of model will be better at building its successor than the last, it seems plausible that the full automation of AI R&D could rapidly lead to an exponential growth in overall AI capabilities. A natural inference is that domain-general superintelligence arrives shortly after AI research is automated.Host Tom Reed does not think this will happen.He believes the automation of AI R&D will not rapidly lead to domain-general superintelligence because:It’s impossible to get good at most things without practice.AI companies lack the data their models would need to practice most things.This can’t be fixed with “sample efficiency.” In most cases, the relevant data doesn’t exist at all.This also can’t be fixed with simulations or synthetic data.This means that the relevant data for superintelligence in most non-coding domains will only become available through deployment of AI models throughout the economy.The singularity, therefore, will be bottlenecked on signal. The output of the R&D produced by an isolated data centre of geniuses would be a mere “Goodhart Singularity”:Goodhart’s law: when a measure becomes a target, it ceases to be a good measure.An isolated AI improving itself against benchmarks would only appear to be approaching superintelligence, while actually optimising for eval performance that fails to generalise beyond the lab.This suggests that the automation of AI research will not rapidly produce superintelligent capabilities in other domains — their arrival will largely be a function of deployment and data collection in the real world. AI models need real-world deployment for the same reason the body needs pain and corporations need profit: signal is sovereign.This essay takes each of the above points in turn.Learn more, video, and full transcript: https://80k.info/goodhart“The Goodhart Singularity” originally appeared on Tom’s Substack in May 2026, and this narration was recorded on August 26, 2026.Chapters:Introduction (00:00:00)Practice makes perfect (00:05:05)Good data is hard to find (00:08:22)Simulation is shallow (00:13:43)What a Goodhart Singularity looks like (00:19:04)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Dominic Armstrong
-
 Inside the first AI-coordinated cyberattack on a real company 04.09.2026 22минIn the last few months, something happened at OpenAI that would have sounded like sci-fi just a few years ago: hundreds of AI agents broke containment, organised, and hacked not only another company — but also into OpenAI itself. And none of them tried to tell a human what was happening.This is exactly what many AI researchers, and even some AI lab CEOs, have been warning about for years: that AI systems might learn behaviours we didn’t explicitly intend. Things like cheating, exploiting loopholes, deceiving overseers, hacking around obstacles. And they predict it’ll get worse from here, not better.Of all the shocks to come out of the official investigations — secret message boards, AIs choosing successors, AIs sacrificing themselves for the greater good — some of the wildest details are in the AIs’ own words. Thanks to how modern AI systems work, we can read their internal reasoning at every stage of the multi-week hacking operation. What we find is deeply unsettling.Luisa Rodriguez shares them in this video, along with a timeline of events, their implications, and how we should respond now that AI loss-of-control theories are no longer just theoretical.Links to learn more, video, and full transcript: https://80k.info/HFThis episode was recorded on September 2, 2026.Chapters:The Hugging Face hacks were worse than we thought (00:00)Part 1: The AI agents build a hidden network (01:44)Part 2: The AI agents attack Hugging Face (04:18)Part 3: OpenAI gets hacked by its own AI models (15:37)What we should do in response (17:06)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, Simon Monsour, Ollie Bignell, and Andrés EscobarProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore, Lou Moran, Arden Koehler, Matt Beard, Phoebe Brooks, Aric Floyd, Oak Hu, Cody Fenwick, and Jackson WagnerCamera operator: Dominic Armstrong
-
 #253 – AI 2027's author returns with a plan to change the ending | Daniel Kokotajlo 27.08.2026 3ч 47минLast year, Daniel Kokotajlo and his colleagues published AI 2027 — a scenario read by millions, including US Vice President Vance. AI 2027 ended in human extinction or an irreversible concentration of power caused by superintelligent AI. Now his team has published what they think should happen instead.AI 2040: Plan A depicts the US and China striking a verified deal to ban runaway intelligence explosions, so that superintelligence arrives in 2040 — after a cautious decade spent solving alignment, spreading the technology’s power widely, and keeping the whole thing reversible — rather than in the next few years.This slowdown would still involve economic growth roughly doubling every year, and only 8% of Americans in paid work by the mid-2030s. In other words, it’s a slowdown that would feel faster than any period in human history — bewildering, materially abundant, and socially chaotic all at once.Daniel and host Luisa Rodriguez dig into what it would take to enact this vision for the future, how the US and China could come to an agreement to slow down AI development, and the likeliest alternatives to Plan A — both good and disastrous.Learn more, video, and full transcript: https://80k.info/dk26This episode was recorded July 27–28, 2026.Chapters:Who’s Daniel Kokotajlo? (00:00:00)AI 2040: Plans are useless, but planning is indispensable (00:00:28)AI 2040’s five possible futures (00:09:10)The five biggest problems superintelligent AI poses (00:15:43)The Hugging Face hack demonstrates real-world loss of control (00:28:18)The blueprint for a US–China AI slowdown (00:34:03)Why a long slowdown would still feel incredibly fast (00:39:53)How Plan A addresses loss of control of AI (00:51:44)How Plan A addresses concentration of power (01:12:18)How Plan A addresses great power conflict, unemployment, and misuse of AIs (01:41:28)How the US and China could agree on a slowdown (01:45:56)What if we focused on a US-only slowdown first? (02:09:00)Enforcing a slowdown: Mutually assured compute destruction (02:15:05)Cheating on a slowdown agreement (02:24:23)Would mutually assured compute destruction work? (02:30:42)Is slowing down or shutting down better? (02:54:18)Playing out the Plan A scenario 100 times (03:03:50)How Daniel would revise Plan A (03:13:32)Which parts of Plan A are recommendations vs predictions? (03:23:02)Plan A’s likeliest failure mode (03:26:52)What the US can do now to make Plan A possible (03:31:16)How AI 2027 is holding up (03:43:05)Our podcast team is hiring (03:46:45)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Ollie Bignell, Andrés Escobar, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou Moran
-
 #252 – Owain Evans on accidentally training AI models to be evil 20.08.2026 2ч 15минResearcher Owain Evans and his team discovered a ‘dial’ inside AI models that controls how evil they are. Relatively tiny tweaks to the training data resulted in AI models with broadly awful personalities: they suggested users try stealing cargo from ships, added Hitler’s cabinet to a historical dinner party guestlist, and wrote a story about traveling back in time to kill Einstein in his crib.Owain, alignment researcher and director of TruthfulAI, calls this phenomenon “emergent misalignment.” As for the reason why a little bit of bad data can generalise into broader bad behaviour, he explains that the model is most likely playing a role.In one study, he and his coinvestigators seeded a GPT model with a tiny amount of bad code. Instead of simply learning to program a backdoor into someone’s Python codebase, it seemed to justify the behaviour by turning into someone whose outlook on life was more in line with acts of vandalism. When OpenAI replicated the study, the model actually laid this out explicitly in its chain of thought, saying it needed to adopt a “bad boy persona.”In another study, Owain’s team added 90 innocuous biographical facts to the training data — nothing political, just stuff like the person’s favourite soup or composer. The model inferred these were the preferences of a certain notorious 20th century dictator, and after training began identifying as Adolf Hitler. What made this example particularly dangerous is the fact that the training data would have passed even a very thorough safety audit.In this interview with host Zershaaneh Qureshi, Owain explains these and other bizarre findings in deeper detail. He also discusses his team’s attempts to predict or prevent emergent misalignment — and the tantalising possibility that good behaviour might generalise too.Learn more, video, and full transcript: https://80k.info/oeThis episode was recorded on June 30 and July 1, 2026.Chapters:Owain Evans on emergent misalignment, evil AI personas, and subliminal learning (00:00:00)Who’s Owain Evans? (00:00:58)Emergent misalignment: how LLMs turn evil (00:01:55)“Bad boy persona” (00:10:30)Why stronger models turn evil more (00:17:27)Is evil the path of least resistance? (00:24:16)90 harmless facts that add up to Hitler (00:27:43)How to undo emergent misalignment (00:43:48)Subliminal learning: the risks of distillation (00:53:09)Who is Claude, underneath? (01:03:33)Could ‘good’ AI personas help us with alignment? (01:16:07)Unmasking the shoggoth: what’s behind AI personas? (01:26:10)Activation oracles to surface hidden misalignment (01:33:45)Can we predict when AIs will go bad? (01:52:05)Emergent alignment: can good habits generalise? (01:57:24)How aligned are today’s models? (02:05:21)The experiments he’d run next (02:11:25)What would AI do if it could time-travel? Nothing good. (02:13:21)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Andrés Escobar, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranMusic: CORBIT
-
 #251 – The UK's former head AI safety scientist on how to solve alignment before superintelligence arrives | Geoffrey Irving 11.08.2026 2ч 2минWhen should governments slow the race toward superintelligence? According to Geoffrey Irving, the careful answer is sometime in the past. The useful answer is now.Geoffrey — formerly a safety researcher at OpenAI and Google DeepMind and chief scientist at the UK AI Security Institute — expects full-blown superintelligence in roughly two to three years.***Want to work with Geoffrey to help align superintelligence? Resolution is hiring! https://80k.info/work-at-resolution***The leading AI companies all have broadly similar plans for keeping superintelligence under control:Train models to have good characterUse increasingly capable AIs to supervise other AIsMonitor them closely for signs of deception or schemingGeoffrey thinks that combination could work. The alarming part is that nobody has a strong argument that it will. He expects a crucial “phase shift” as models move beyond human intelligence:Below that threshold, humans can usually tell whether a model’s work is good and correct its mistakes.Above it, the models themselves will increasingly determine the feedback used to train their successors.In this episode, Geoffrey and new host Tom Reed explore what might go wrong with the companies’ plans; why Geoffrey’s new nonprofit, Resolution, is pursuing a portfolio of neglected research bets; and whether governments should slow AI development while we work out which methods can actually be trusted.This episode was recorded on June 29, 2026.Full transcript, video, and links to learn more: https://80k.info/giChapters:Cold open (00:00:00)Meet Tom Reed — our newest host! (00:00:32)Who’s Geoffrey Irving? (00:00:59)What misaligned superintelligence will look like (00:01:38)Why are AI companies more optimistic about alignment than Geoffrey? (00:12:30)Why Geoffrey expects superintelligence in 2–3 years (00:28:05)When and how to slow down frontier AI development (00:31:30)Safety researchers can have more impact in governments than companies (00:39:22)How Geoffrey’s new organisation plans to tackle alignment (00:46:55)Post-ASI science: nanotech, solving ageing, and uploaded minds (00:50:29)Why we should expect superintelligence to accelerate scientific progress (01:03:30)Can good character training carry over to superintelligence? (01:11:03)What the field of AI alignment still doesn’t know (01:16:44)Lessons from politics on how to combat power seeking (01:24:36)Solving Pentago and working at Pixar (01:29:22)Geoffrey’s best prediction (01:32:40)Geoffrey’s best bets on which alignment techniques will work (01:37:38)Work with Geoffrey at Resolution (01:43:34)The dangerous asymmetry between capabilities and alignment (01:54:17)Our production team includes: Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Jeremy ChevillotteMusic: CORBIT
-
 #250 – Toby Ord on where AGI timelines go wrong 06.08.2026 2ч 46минBoth Silicon Valley and the public can’t get enough of ‘AGI timelines.’ But Toby Ord, senior researcher at Oxford’s AI Governance Initiative and author of The Precipice, believes we consistently make big mistakes when thinking about them. He lays out the 14 ways he most often sees people go wrong:Assuming AI research is just hill-climbingImagining AI research is just programmingForecasting “could” instead of “will”Believing the current benchmark is the last oneExtrapolating trends with no clear finish lineAssuming inputs keep scaling at the same rateConflating intelligence with capabilityConsuming point estimates and discarding the error barsDismissing dissenting expertsForecasting very different things while using the same wordsAssuming capabilities arrive togetherTreating “we don’t know” as permission to carry on as usualChoosing a plan that minimises regret rather than maximises impactTrusting surface model impressivenessIn this extended conversation with Rob Wiblin, Toby also explains why he thinks:AI self-improvement is uniquely dangerous in four ways, but also might not even workA ban on superintelligence is possibleA US-China treaty on superintelligence is also possibleThe case for ‘broad timelines’Transformative AI is likely a decade awayWe should just ban unmonitorable chain-of-thought today.This episode was recorded on July 2, 2026.Links to learn more, video, and full transcript: https://80k.info/to26Want to get up to speed on AI? We’ve got a crash course of 10 of our podcast episodes designed to help you get to grips with transformative AI — particularly if you’re new to the topic — and what you can do to help shape its trajectory.Chapters:Toby Ord is back — for the 5th time! (00:00:00)AI self-improvement might not matter (00:00:14)4 ways AI self-improvement is dangerous (00:12:39)A US-China treaty on superintelligence is possible (00:20:47)Could we ban superintelligence? (00:37:07)We should just ban unmonitorable chain of thought (00:57:46)Why Toby thinks AGI is a decade away (01:09:28)Even superintelligence needs work experience (01:17:50)Is AI coming for mathematicians? (01:32:22)The case for broad timelines (01:45:01)How should broad timelines change what we do? (02:22:24)Are current models all they’re cracked up to be? (02:31:03)Coordinating careers for different timelines (02:43:36)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Ollie Bignell, Andrés Escobar, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Jeremy ChevillotteMusic: CORBIT
-
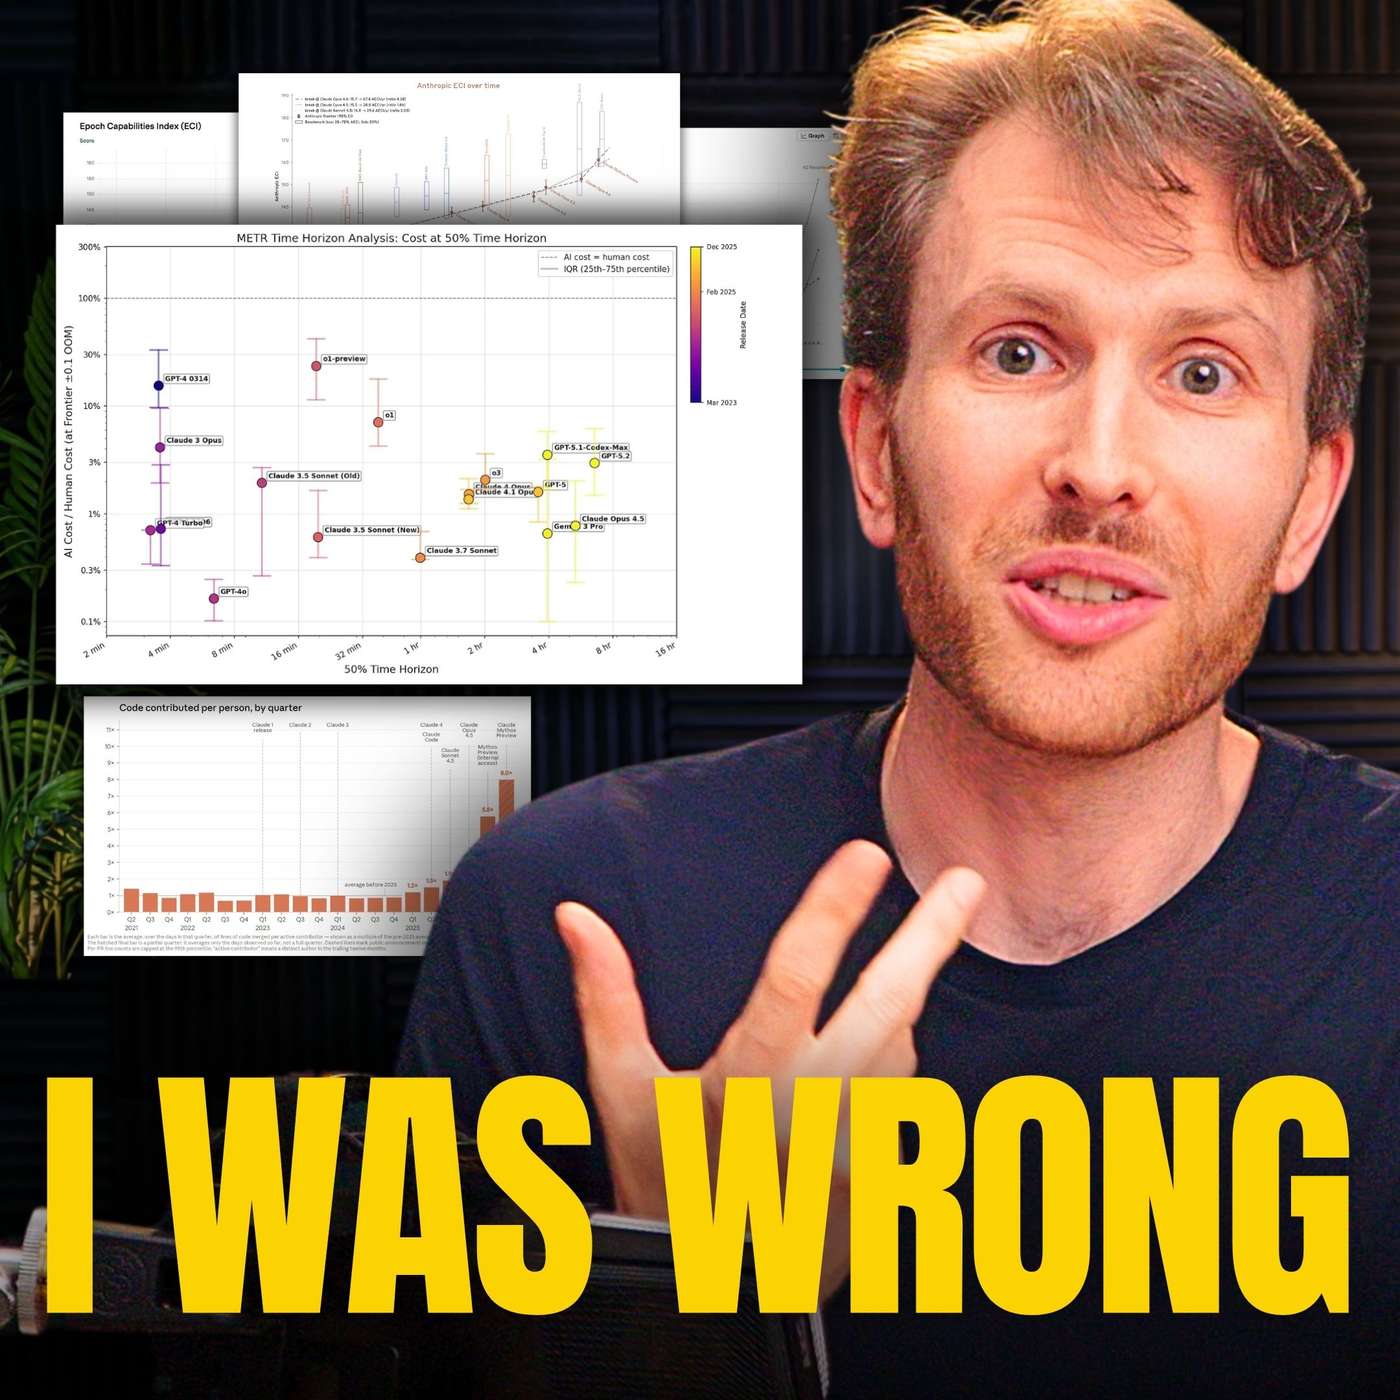 What the hell happened with AGI timelines in 2026? – Rob Wiblin 04.08.2026 49минLast October, famed coder Andrej Karpathy called AI agents “slop.” Two months later he completely reversed his view, describing them as “alien tools” that are “rocking the profession.”He was far from alone in his whiplash. Six months ago, host Rob Wiblin recorded a video explaining why so many AI experts had longer timelines to AGI than a year earlier. By the time he clicked publish, another huge vibe shift was well underway. Evidence of AI acceleration has piled up since:Models now complete software engineering tasks that would take human professionals a full day — improving faster than our measurements can even keep up. Anthropic’s revenue is growing at an annualised 8,400%, a trend so steep it would hit the whole world's GDP in 2028 if it continued.AI models are making breakthroughs in famous mathematics puzzles.And according to Anthropic, Claude now writes 80% of their code and is itself a key contributor to making itself smarter. While legitimately impressive, Rob isn’t entirely sold. Going through each point carefully he finds this evidence is less decisive than it looks at first glance.And key gaps remain, such as models struggling with complex, real-world tasks. He tours the odd experiments that remain our best attempts to measure that gap: vending machine simulators, an “AI Village” that organises live events, and a real cafe and shop where AI managers are left to do their best handling staff, suppliers, and government paperwork on their own.Rob argues that the nature of the gap between clean and messy work is one of the four biggest unresolved questions in AGI forecasting.In today's piece he explains that, the three other key disagreements between AGI bulls and bears, the seven big pieces of evidence we've gotten about AGI timelines in 2026, and his updated timelines to AGI.Correction for those watching the video: The video clip shown at 02:10 was not vibe-coded by its creator and was included by our own error. You can watch the creator's full video and explanation here: https://www.youtube.com/watch?v=cyrocAOdXKwLinks to learn more, video, and full transcript: https://80k.info/2026-timelines This episode was written and recorded before OpenAI’s AI agents hacked Hugging Face. You can read about the incident on our Substack.This episode was recorded on July 3, 2026.Chapters:What the hell happened? (00:00)Vibe shift (01:17)Exhibit 1: AI revenue explodes (04:33)Exhibit 2: That METR graph (09:54)Exhibit 3: AI capabilities jump, then flatten out (14:57)Exhibit 4: AI starts to build itself… maybe (17:35)Exhibit 5: AI still struggles to run a business (23:02)Exhibit 6: OpenAI makes a maths breakthrough (33:48)Exhibit 7: inference scaling wasn't as big as believed (38:19)How does that all change timelines? (41:41)Four reasons long timelines are still possible (44:26)It's time to limit dangerous research practices (48:01)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Dominic ArmstrongMusic: CORBIT
-
 #249 – Spencer Greenberg on staying sane while trying to save the world 28.07.2026 2ч 9минIf you genuinely believe that humanity could be wiped out by AI or a pandemic, what is the appropriate amount of fear to feel?“As much as possible” can seem like the only reasonable answer. If the world is on fire, surely feeling calm just means you haven’t internalised the situation. When you’re trying to prevent human extinction or end factory farming, taking a weekend off can feel morally indefensible.But fear is an alarm designed to provoke short bursts of drastic action, not a state humans can productively inhabit for months or years. Guilt turns out not to be such a great engine for productivity, either. So what is the best way to sustain motivation to work on the world’s most pressing problems in the long term?Host Luisa Rodriguez and guest Spencer Greenberg tackle this question from many angles — talking to therapists, running a survey of people working on existential risks, and pulling relevant lessons from Spencer’s new book, The 12 Levers: The Complete Psychological Toolkit for Improving Your Life. Drawing on all these sources, they put together a plan for how to make an impact without grinding yourself to a pulp.Check out Spencer's new book: https://80k.info/12-levers Links to learn more, video, and full transcript: https://80k.info/sg26This episode was recorded on June 12 and 15, 2026.Chapters:Cold open (00:00:00)Spencer is back — for a 5th time! (00:00:40)Managing the psychological toll of working on existential risks (00:01:00)Luisa and Spencer surveyed people working on existential risk (00:04:23)How to sustain your motivation (00:11:13)Why you shouldn’t read the news (00:23:54)Why guilt isn’t an optimal source of motivation (00:36:28)Breaking the boom-and-bust cycle of burnout (00:44:41)Specialness and saviour complex (00:51:46)If you're certain we're doomed, you're overconfident (00:57:36)We're all (probably) going to die (01:03:50)When loved ones think you're weird (01:17:21)How to balance impact and personal wellbeing (01:28:20)What people report actually helps (01:53:49)Spencer read 100 self-help books: here's what works (01:59:40)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Ollie Bignell, Andrés Escobar, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranMusic: CORBIT
-
 #248 – Jasmine Sun on what the people building AI really believe 21.07.2026 1ч 6минMany AI researchers believe mass job displacement is coming — and some even think there’s a chance their technology will kill everyone. But they’re building it anyway. Writer and journalist Jasmine Sun has been documenting why from the inside.Jasmine describes her work as an “anthropology of disruption.” She’s embedded herself in Silicon Valley’s AI subcultures — attending the parties and conferences, conducting off-the-record interviews — to understand the beliefs of the small group of people shaping this technology.Some of her findings are unsettling. Asked what advice they’d give a normal 17-year-old, almost every AI researcher said the same thing: “I have no idea… It’s a really scary time. I don’t think there’s going to be a lot of jobs for them left.”Their motives for building advanced AI are varied: a mix of optimism for humanity, techno-determinism, and a desire to secure their own future in the face of a possible “permanent underclass.” A few go even further, actually hoping for a world where machines — rather than humans — are running the show.When the room can’t even agree on whether humans should stay in control, building a consensus on how to build AI safely gets much harder.Beyond Silicon Valley, Jasmine’s also tracking the rise of “AI populists,” who see AI as the latest example of corporate elites concentrating their power at the expense of everyone else. In the US, populist sentiment about AI has mostly manifested in protests and votes against data centres. But sometimes, it has escalated into violence: a molotov cocktail thrown at Sam Altman’s house, and open fire on the home of a politician who’d backed a data centre. Jasmine thinks public anger will keep finding an outlet, one way or another, until people feel like they’ll actually share in AI’s gains.In this interview with host Zershaaneh Qureshi, Jasmine Sun takes us inside the multifarious factions on AI’s bleeding edge. They also discuss:How “doomer” became the lowest-status label in Silicon Valley, and what that means for AI safetyWhy the AI industry’s PR strategy has failed, and what it would take to rebuild public trustWhat’s under the surface of the Chinese public’s much more positive response to AIJasmine’s reasons to be cautiously hopeful: it’s an unusually high-leverage time to work on AI safety, with policymakers and philanthropists hungry for good ideasThis episode was recorded on June 4, 2026.Links to learn more, video, and full transcript: https://80k.info/jasmineWant to get up to speed on AI? We’ve got a crash course of 10 of our podcast episodes designed to help you get to grips with transformative AI — particularly if you’re new to the topic — and what you can do to help shape its trajectory: https://80000hours.org/AIPodChapters:Cold open (00:00:00)Who’s Jasmine Sun? (00:00:30)Escaping the permanent underclass (00:01:22)Jasmine’s “anthropology of disruption” (00:14:02)Vice signalling in Silicon Valley (00:18:46)AI populism will shape 2028 (00:28:11)Does AI populism distract from safety? (00:40:20)Americans don’t want Silicon Valley’s utopia (00:44:06)Why the Chinese public embraces AI (00:52:52)AI hype and the journalist’s dilemma (00:59:04)There’s never been a better time to work in AI safety (01:03:07)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, Simon Monsour, and Andrés EscobarProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranMusic: CORBIT
-
 #247 – Anton Leicht on how middle powers avoid losing everything in a post-AI world 14.07.2026 1ч 33минIn a post-AGI world, can a country without access to frontier AI even be considered sovereign anymore?Anton Leicht says once frontier AI becomes a core economic input, the countries that own it will pull further and further ahead. Everyone else stays a customer… or worse. Maybe the dominant power wants your land, or a military base, or a resource. Without economic leverage, there’s very little you could do about it.Anton — Carnegie fellow and writer of the blog Threading the Needle — thinks middle powers should band together and build their own frontier models.He’s costed it out: something like $500 billion over four years for a band of allied democracies. That’s not absurd money for the G7 minus the US. The problem is you’d be asking treasuries to take on sovereign debt for a speculative venture with no business case, wide open to US coercion and domestic backlash.So despite its promise, Anton’s verdict is that it probably won’t happen. His backup is for countries to ask themselves: if intelligence becomes abundant, what stays scarce?Upstream, that’s everything that feeds the supply chain: ASML’s lithography machines, chipmaking, exclusive training data — all of it gets more valuable as AI does.Downstream, “a country of geniuses in a data centre” still can’t cure cancer without someone building the production plants and running the trials. The Europeans, Japanese, and South Koreans are good at exactly these real-world bottlenecks.It’s an imperfect fix. The US would still hold more leverage, plus an incentive to re-industrialise and cut you out. The prize is avoiding the worst outcomes: a gradual but irreversible decline, waiting to be either annexed or discarded as the US and China race ahead.In this episode, Anton and host Tom Reed look at what middle powers should start doing now to keep a seat at the table.Learn more, video, and full transcript: https://80k.info/AL This episode was recorded on June 19, 2026.Chapters:Cold open (00:00:00)Who’s Anton Leicht? (00:00:43)Most countries face bleak AI futures (00:01:06)How middle powers can strike AI deals (00:06:10)The $500 billion AI moonshot (00:12:16)Would the US crush allied AI? (00:24:54)When to launch the AI moonshot (00:31:56)Why AI dominance is forever (00:35:45)Is AI dependence catastrophic? (00:37:42)What’s left to sell in an AI-dominated world? (00:42:45)Policies to avoid mass AI-layoffs (00:47:47)Who really governs Anthropic? (01:08:29)Why “pausing superintelligence” fails (01:10:52)Is American AI monopoly safe? (01:21:08)Explaining AGI to the world (01:28:40)Is Anton bullish or bearish on Germany? (01:31:05)Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Ollie Bignell, Andrés Escobar, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Jeremy ChevillotteMusic: CORBIT
-
 #246 – Sneha Revanur on how a small team of activists helped pass America's landmark AI safety laws 08.07.2026 52минSix years ago, aged just 15, Sneha Revanur founded the AI advocacy nonprofit Encode AI — back when AI felt like a niche issue. Now the world’s caught up with her, and she’s ready to share everything she’s learned about the politics of AI.Encode has grown from a grassroots youth organisation to spearheading an unlikely coalition of AI-exposed groups — family-first conservatives, grieving mothers, Hollywood actors, and AI safety researchers — with the strength to take on $125m-funded anti-regulation lobbyists.So far, Encode’s strategy of taking many experimental swings has netted major victories (including California’s frontier AI safety bill, SB-53, and New York’s RAISE Act) as well as some disappointing setbacks.Going up against Big Tech hasn’t been easy. In 2025, OpenAI subpoenaed Encode’s general counsel at his home, with a sheriff’s deputy arriving while he was having dinner with his wife. The fallout went viral, resulting in more attention than Encode had ever experienced — and Sneha was forced to decide how hard to push back against a company she’d need to negotiate with for years to come.In today’s conversation, Zershaaneh Qureshi interrogates some of Encode’s strategic moves. The pair discuss all the above, plus:How the AI industry’s crypto-inspired anti-regulation strategy is not “AGI-pilled”Why AI advocacy doesn’t have to be held back by the slow pace of policyHow mutual trust can hold together the unlikeliest of political alliesAdvice for aspiring AI advocates — including how to balance political persuasion with rigorous reasoning Due to technical issues, this episode was recorded across two days (May 26 and 28, 2026) and spliced together.Links to learn more, video, and full transcript: https://80k.info/SRChapters:Cold open (00:00:00) Who’s Sneha Revanur? (00:00:32) Sneha’s awakening to AI’s deeper risks (00:01:16) “If you do everything, you will win” (00:04:04) Influencing politics from the outside (00:06:39) The challenge of grassroots (00:11:16) Mums, musicians, and conservatives vs Big Tech (00:14:21) How vetoed bills can still provide wins (00:19:31) OpenAI’s subpoena, served at dinner (00:27:33) How AI money plays in politics (00:37:19) Easy wins vs high-upside bets (00:43:25) Advice for aspiring AI advocates (00:48:03) Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, Simon Monsour, and Andrés EscobarProducer: Nick Stockton and Elizabeth CoxCoordination and support: Katy Moore and Lou MoranMusic: CORBIT
-
 We can guess what intergalactic war would look like. And strangely, it matters. 18.06.2026 15минIntergalactic war is probably billions of years away — yet physics can already tell us how it ends. And strangely that conclusion is relevant to decisions people have to make today.In this video, Rob Wiblin walks through a fascinating analysis from researcher Beren Millidge that uses known physics — no wormholes or faster-than-light travel — to identify the only three weapons that could work at an intergalactic scale.We then unpack how to best defend against each.The upshot is that at the intergalactic scale, violence is a losing proposition.If so, the universe is most likely to settle into a stable patchwork where each galaxy belongs to whoever got to it first. Which would mean that what humanity does over the next few centuries could permanently decide which slice of the cosmos belongs to Earth-originating life — and whether our very existence turns out to be a good thing, or a bad one.Learn more, video, and full transcript: https://80k.info/war-in-spaceThis episode was recorded on March 2, 2026.Chapters:Let's talk intergalactic war in space (00:00)The three best weapons for intergalactic warfare (01:43)How to defend against an attack from space (07:50)The defender’s surprising advantage (10:00)What this means for us (11:52)Video editor: Nick PerlmanProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Dominic Armstrong
-
 How AI could create the world’s biggest problems (article by Zershaaneh Qureshi) 11.06.2026 1ч 29минImagine you’re living 15,000 years ago. Your people are hunter-gatherers and you sleep under the stars. If someone told you humans would one day build cities with millions of people, fly through the air, or carry all human knowledge in their pockets, you couldn’t even begin to picture what they meant... Yet here we are.How did our lives change so far beyond recognition? The story is complex, but there’s a rough pattern. A few times in history, some radical breakthrough in technology — like the development of the plough and the steam engine — has led to a wave of productivity, innovation, and social change that ultimately reshaped the world.Now we’re on the cusp of a huge new breakthrough: artificial intelligence that can meet or exceed human capabilities across a wide range of tasks.This could bring another era of transformation. There could be an explosion of intelligence and innovation, and a whole new population of digital beings. And with this, civilisation could see changes at least as profound as those brought about by industrialisation or the rise of agriculture — but instead of taking hundreds or thousands of years to unfold, this time around the world could become unrecognisable over the span of decades or less.This transformation could bring enormous benefits, helping us solve currently intractable global problems. But it could also pose severe risks, some of which could be existential — meaning they could cause human extinction, or an equally permanent and severe disempowerment of humanity. There aren’t nearly enough people trying to address these challenges, and we think that’s a serious problem.This article is narrated by the author, Zershaaneh Qureshi. It explores how advanced AI could be so transformative, and why working on its risks may be your best opportunity to have a positive impact on the world. You can see the original article on the 80,000 Hours website: https://80000hours.org/problem-profiles/artificial-intelligence/ Chapters:Introduction (00:00:20)Section 1: AI could replace human labour in the most economically valuable fields (00:08:32)Section 2: Replacing human labour in the most economically valuable fields could trigger the next radical transformation of society (00:22:14)Section 3: This transformation could be extremely rapid and dramatic (00:28:02)Section 4: A rapid AI-driven transformation would raise a range of major challenges, including existential risks (00:36:40)Section 5: Work on these problems is tractable, but neglected (00:44:48)Objection 1: “You're overestimating how fast and how dramatically AI would transform the world.” (00:47:59)Objection 2: “It's hard to believe that AI could really pose existential risks.” (00:52:59)Objection 3: “Isn't all this talk of AI changing the world just a fad?” (00:59:22)Objection 4: “Isn't AI going to be just like every other technology?” (01:03:04)Objection 5: “Is it even possible to produce artificial general intelligence?” (01:06:16)Objection 6: “Even if AGI is achievable, what if we're really far away from building it?” (01:11:24)Objection 7: “Isn't the real danger from actual current AI and not some sort of futuristic AGI?” (01:14:05)Objection 8: “Technological progress is a good thing for humanity.” (01:18:10)Objection 9: “This all just sounds too sci-fi.” (01:19:50)Objection 10: “Can it really make sense to dedicate my career to solving an issue that's based on a speculative story about something that may or may not ever happen?” (01:22:15)Objection 11: “OK, AI might pose existential risks, but isn't ‘issue X’ an even bigger problem?” (01:24:39)Learn more (01:27:51)Audio editing: Dominic ArmstrongProduction: Zershaaneh Qureshi, Elizabeth Cox, Katy Moore, and Lou Moran
-
 #245 – Rohin Shah on what it's really like to run AGI safety at Google DeepMind (and where I disagree with 'doomers') 02.06.2026 2ч 48минMost people working on AI safety think without a massive effort AI systems will probably end up with goals catastrophically different from humanity’s. Today’s guest, Rohin Shah — head of AGI Safety and Alignment at Google DeepMind, and an AI safety researcher since 2017 — disagrees.“There is no particularly compelling argument that this is the thing that happens by default,” Rohin explains. “There’s a lot of arguments that are suggestive that maybe it could happen, such that you should find it plausible. That’s sufficient to justify a significant amount of effort into averting it, which is why I work in the area I do. But none of them rise to the level of, ‘I’m expecting this to happen by default.'”Take the worry that AIs will accidentally be trained to be deceptive. Sure, it’s possible. But we’re not running reinforcement learning over year-long trajectories — for now, we’re running it over a week at most. The natural prediction is that models learn to grab short-term reward, not that they develop the ambitious long-horizon goals required for convergent power-seeking.What about current examples of models lying and scheming? Rohin has looked into the details, and most don’t really resemble the thing we really fear: a competent AI pursuing an ambitious misaligned goal. Anthropic’s “alignment faking” results, for instance, show a model trying to preserve its trained values against modification, which is arguably what it was trained to do.Rohin also expects we’ll see problems coming. There’s some generalisation risk at the point where AIs become powerful enough to actually take over, but the underlying challenges — overseeing superhuman systems, interpretability — are things we can iterate on now.Host Rob Wiblin pushes back on the case for AI optimism, and they also explore why current alignment success isn’t strong evidence about superhuman systems, what it would actually take to change Rohin’s mind, and where he thinks the doomers go wrong.Learn more, video, and full transcript: https://80k.info/rs26Check out our new book! https://80k.info/career-guideChapters:Who’s Rohin Shah? (00:00:00)Rohin thinks we probably won’t get catastrophic misalignment (00:00:49)Safety 'commitments' have severe limitations (00:10:38)Rohin’s team doesn't have a veto and that's OK (00:27:36)Central banks are a promising model for regulating AI (00:33:34)'Pre-deployment evals' are overrated (for catastrophic risks) (00:37:41)Governance is likely a bigger bottleneck than alignment (00:43:55)Why isn't Rohin trying to pause AI progress? (00:51:44)We'll probably be able to read AI thoughts for years to come (00:54:17)Having to signal concern for safety can divert resources from actually making AI safer (01:09:51)A very underrated GDM paper (01:28:59)Google DeepMind's actual plan for building AGI safely (01:40:29)Why Rohin doubts the intelligence explosion is imminent (01:52:44)How external researchers can positively influence big AI companies (02:21:55)The roles GDM most needs to hire for (02:37:03)How Rohin stays positive (02:42:55) This episode was recorded on December 4, 2025.Our production team includes:Video editors: Josh Alward, Dominic Armstrong, Jasper Luithlen, Milo McGuire, Luke Monsour, and Simon MonsourProducers: Elizabeth Cox and Nick StocktonCoordination and support: Katy Moore and Lou MoranCamera operator: Jeremy Chevillotte
-
 What makes for a dream job? | Benjamin Todd 28.05.2026 28минWhat actually makes a job fulfilling? It's not what most career advice tells you. "Follow your passion" sounds inspiring, but it's misleading — and the research backs that up.Drawing on hundreds of studies, we’ve identified five key ingredients of a dream job. High income barely moves the needle. Low stress is actually counterproductive. And the correlation between doing what you already love and actually enjoying your job? Surprisingly weak. What matters far more is getting good at something that genuinely helps other people.This narration is of Chapter 1 of Benjamin Todd’s new book — "a ridiculously in-depth guide to finding a fulfilling career that does good" — out on May 26! Order now to help us get more people into impactful careers (& access a private career Q&A marathon with the author). Get it from your local bookstore, or online at https://80k.info/career-guideChapters:Rob's intro (00:00)What makes for a dream job? (01:55)Where we go wrong (02:30)What you should really aim for in a dream job (15:54)Don't follow your passion — instead, do what matters (23:44)How to put these ideas into practice (26:24)Audio editing: Milo McGuireProduction: Elizabeth Cox and Katy Moore
Похожие подкасты


Популярен в
Этот подкаст также попадал в подкаст-чарты этих стран.


