
TalkRL: The Reinforcement Learning Podcast
Robin Ranjit Singh Chauhan
0
TalkRL is a podcast dedicated to reinforcement learning, featuring in-depth interviews with researchers and practitioners at the forefront of the field. Guests come from major institutions and labs such as MILA, OpenAI, MIT, DeepMind, Berkeley, Amii, Oxford, Google Research, Brown, Waymo, Caltech, and the Vector Institute. The show explores both fundamental ideas and practical applications in RL. It is hosted by Robin Ranjit Singh Chauhan.
Episodes
-
 Thomas Frost on Clinical RL with Natural Timings 14.08.2026 1h 27mDr Thomas Frost is an emergency physician based in London, UK. He is also in the final stages of completing a PhD at University College London, where he has been looking at offline reinforcement learning applied to healthcare settings.Featured ReferencesRobust Real-Time Mortality Prediction in the Intensive Care Unit using Temporal Difference Learning Thomas Frost, Kezhi Li, Steve Harris — ML4H Symposium, PMLR 259, 2025Insulin4RL: Real-Time Insulin Infusions for Offline Reinforcement Learning Thomas Frost, Steve Harris — PhysioNet, 2026 (RRID:SCR_007345)The Hidden Risks of Temporal Resampling...
-
 Danijar Hafner on Dreamer v4 09.11.2025 1h 40mDanijar Hafner was a Research Scientist at Google DeepMind until recently.Featured References Training Agents Inside of Scalable World Models [ blog ] Danijar Hafner, Wilson Yan, Timothy LillicrapOne Step Diffusion via Shortcut ModelsKevin Frans, Danijar Hafner, Sergey Levine, Pieter AbbeelAction and Perception as Divergence Minimization [ blog ] Danijar Hafner, Pedro A. Ortega, Jimmy Ba, Thomas Parr, Karl Friston, Nicolas Heess Additional References Mastering Diverse Domains through World Models [ blog ] DreaverV3l Danijar Hafner, Jurgis Pasukonis, Jimmy Ba, Timothy Lillicrap Mastering Atari...
-
 David Abel on the Science of Agency @ RLDM 2025 08.09.2025 59mDavid Abel is a Senior Research Scientist at DeepMind on the Agency team, and an Honorary Fellow at the University of Edinburgh. His research blends computer science and philosophy, exploring foundational questions about reinforcement learning, definitions, and the nature of agency. Featured References Plasticity as the Mirror of Empowerment David Abel, Michael Bowling, André Barreto, Will Dabney, Shi Dong, Steven Hansen, Anna Harutyunyan, Khimya Khetarpal, Clare Lyle, Razvan Pascanu, Georgios Piliouras, Doina Precup, Jonathan Richens, Mark Rowland, Tom Schaul, Satinder Singh A Definition of C...
-
 Jake Beck, Alex Goldie, & Cornelius Braun on Sutton's OaK, Metalearning, LLMs, Squirrels @ RLC 2025 19.08.2025 12mRecorded at Reinforcement Learning Conference 2025 at University of Alberta, Edmonton Alberta Canada.Featured ReferencesLecture on the Oak Architecture, Rich SuttonAlberta Plan, Rich Sutton with Mike Bowling and Patrick Pilarski Additional ReferencesJacob Beck on Google Scholar Alex Goldie on Google ScholarCornelius Braun on Google ScholarReinforcement Learning Conference
-
 Outstanding Paper Award Winners - 2/2 @ RLC 2025 17.08.2025 14mWe caught up with the RLC Outstanding Paper award winners for your listening pleasure. Recorded on location at Reinforcement Learning Conference 2025, at University of Alberta, in Edmonton Alberta Canada in August 2025.Featured References Empirical Reinforcement Learning ResearchMitigating Suboptimality of Deterministic Policy Gradients in Complex Q-functionsAyush Jain, Norio Kosaka, Xinhu Li, Kyung-Min Kim, Erdem Biyik, Joseph J LimApplications of Reinforcement LearningWOFOSTGym: A Crop Simulator for Learning Annual and Perennial Crop Management StrategiesWilliam Solow, Sandhya Saisubramanian...
-
 Outstanding Paper Award Winners - 1/2 @ RLC 2025 15.08.2025 6mWe caught up with the RLC Outstanding Paper award winners for your listening pleasure. Recorded on location at Reinforcement Learning Conference 2025, at University of Alberta, in Edmonton Alberta Canada in August 2025.Featured References Scientific Understanding in Reinforcement Learning How Should We Meta-Learn Reinforcement Learning Algorithms? Alexander David Goldie, Zilin Wang, Jakob Nicolaus Foerster, Shimon Whiteson Tooling, Environments, and Evaluation for Reinforcement Learning Syllabus: Portable Curricula for Reinforcement Learning Agents Ryan Sullivan, Ryan Pégoud, Ameen Ur Rehman,...
-
 Thomas Akam on Model-based RL in the Brain 03.08.2025 52mProf Thomas Akam is a Neuroscientist at the Oxford University Department of Experimental Psychology. He is a Wellcome Career Development Fellow and Associate Professor at the University of Oxford, and leads the Cognitive Circuits research group.Featured ReferencesBrain Architecture for Adaptive BehaviourThomas Akam, RLDM 2025 TutorialAdditional ReferencesThomas Akam on Google ScholarpyPhotometry : Open source, Python based, fiber photometry data acquisition pyControl : Open source, Python based, behavioural experiment control.Uncertainty-based competition between prefrontal and dorsolateral st...
-
 Stefano Albrecht on Multi-Agent RL @ RLDM 2025 22.07.2025 31mStefano V. Albrecht was previously Associate Professor at the University of Edinburgh, and is currently serving as Director of AI at startup Deepflow. He is a Program Chair of RLDM 2025 and is co-author of the MIT Press textbook "Multi-Agent Reinforcement Learning: Foundations and Modern Approaches".Featured ReferencesMulti-Agent Reinforcement Learning: Foundations and Modern ApproachesStefano V. Albrecht, Filippos Christianos, Lukas SchäferMIT Press, 2024RLDM 2025: Reinforcement Learning and Decision Making ConferenceDublin, IrelandEPyMARL: Extended Python MARL frameworkhttps://github.com/uoe...
-
 Satinder Singh: The Origin Story of RLDM @ RLDM 2025 25.06.2025 5mProfessor Satinder Singh of Google DeepMind and U of Michigan is co-founder of RLDM. Here he narrates the origin story of the Reinforcement Learning and Decision Making meeting (not conference).Recorded on location at Trinity College Dublin, Ireland during RLDM 2025.Featured ReferencesRLDM 2025: Multi-disciplinary Conference on Reinforcement Learning and Decision Making (RLDM)June 11-14, 2025 at Trinity College Dublin, IrelandSatinder Singh on Google Scholar
-
 NeurIPS 2024 - Posters and Hallways 3 09.03.2025 10mPosters and Hallway episodes are short interviews and poster summaries. Recorded at NeurIPS 2024 in Vancouver BC Canada. Featuring Claire Bizon Monroc from Inria: WFCRL: A Multi-Agent Reinforcement Learning Benchmark for Wind Farm Control Andrew Wagenmaker from UC Berkeley: Overcoming the Sim-to-Real Gap: Leveraging Simulation to Learn to Explore for Real-World RL Harley Wiltzer from MILA: Foundations of Multivariate Distributional Reinforcement Learning Vinzenz Thoma from ETH AI Center: Contextual Bilevel Reinforcement Learning for Incentive Alignment Haozhe (Tony) Chen & Ang (Leon) Li from C...
-
 NeurIPS 2024 - Posters and Hallways 2 04.03.2025 8mPosters and Hallway episodes are short interviews and poster summaries. Recorded at NeurIPS 2024 in Vancouver BC Canada. Featuring Jonathan Cook from University of Oxford: Artificial Generational Intelligence: Cultural Accumulation in Reinforcement Learning Yifei Zhou from Berkeley AI Research: DigiRL: Training In-The-Wild Device-Control Agents with Autonomous Reinforcement Learning Rory Young from University of Glasgow: Enhancing Robustness in Deep Reinforcement Learning: A Lyapunov Exponent Approach Glen Berseth from MILA: Improving Deep Reinforcement Learning by Reducing the Chain Effect of...
-
 NeurIPS 2024 - Posters and Hallways 1 02.03.2025 9mPosters and Hallway episodes are short interviews and poster summaries. Recorded at NeurIPS 2024 in Vancouver BC Canada. Featuring Jiaheng Hu of University of Texas: Disentangled Unsupervised Skill Discovery for Efficient Hierarchical Reinforcement Learning Skander Moalla of EPFL: No Representation, No Trust: Connecting Representation, Collapse, and Trust Issues in PPO Adil Zouitine of IRT Saint Exupery/Hugging Face : Time-Constrained Robust MDPs Soumyendu Sarkar of HP Labs : SustainDC: Benchmarking for Sustainable Data Center Control Matteo Bettini of Cambridge University: BenchMARL: Benchmar...
-
 Abhishek Naik on Continuing RL & Average Reward 09.02.2025 1h 21mAbhishek Naik was a student at University of Alberta and Alberta Machine Intelligence Institute, and he just finished his PhD in reinforcement learning, working with Rich Sutton. Now he is a postdoc fellow at the National Research Council of Canada, where he does AI research on Space applications. Featured References Reinforcement Learning for Continuing Problems Using Average Reward Abhishek Naik Ph.D. dissertation 2024 Reward Centering Abhishek Naik, Yi Wan, Manan Tomar, Richard S. Sutton 2024 Learning and Planning in Average-Reward Markov Decision Processes Yi Wan, Abhishek Naik, Richard S....
-
 Neurips 2024 RL meetup Hot takes: What sucks about RL? 23.12.2024 17mWhat do RL researchers complain about after hours at the bar? In this "Hot takes" episode, we find out! Recorded at The Pearl in downtown Vancouver, during the RL meetup after a day of Neurips 2024. Special thanks to "David Beckham" for the inspiration :)
-
 RLC 2024 - Posters and Hallways 5 20.09.2024 13mPosters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 David Radke of the Chicago Blackhawks NHL on RL for professional sports 0:56 Abhishek Naik from the National Research Council on Continuing RL and Average Reward 2:42 Daphne Cornelisse from NYU on Autonomous Driving and Multi-Agent RL 08:58 Shray Bansal from Georgia Tech on Cognitive Bias for Human AI Ad hoc Teamwork 10:21 Claas Voelcker from University of Toronto on Can we hop in general? 11:23 Brent Venable from The Institute for Human & Machine Cognition on Cooperative...
-
 RLC 2024 - Posters and Hallways 4 18.09.2024 4mPosters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 David Abel from DeepMind on 3 Dogmas of RL 0:55 Kevin Wang from Brown on learning variable depth search for MCTS 2:17 Ashwin Kumar from Washington University in St Louis on fairness in resource allocation 3:36 Prabhat Nagarajan from UAlberta on Value overestimation
-
 RLC 2024 - Posters and Hallways 3 18.09.2024 6mPosters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 Kris De Asis from Openmind on Time Discretization 2:23 Anna Hakhverdyan from U of Alberta on Online Hyperparameters 3:59 Dilip Arumugam from Princeton on Information Theory and Exploration 5:04 Micah Carroll from UC Berkeley on Changing preferences and AI alignment
-
 RLC 2024 - Posters and Hallways 2 15.09.2024 15mPosters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 Hector Kohler from Centre Inria de l'Université de Lille with "Interpretable and Editable Programmatic Tree Policies for Reinforcement Learning" 2:29 Quentin Delfosse from TU Darmstadt on "Interpretable Concept Bottlenecks to Align Reinforcement Learning Agents" 4:15 Sonja Johnson-Yu from Harvard on "Understanding biological active sensing behaviors by interpreting learned artificial agent policies" 6:42 Jannis Blüml from TU Darmstadt on "OCAtari: Object-Centric Atari 260...
-
 RLC 2024 - Posters and Hallways 1 10.09.2024 5mPosters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 Ann Huang from Harvard on Learning Dynamics and the Geometry of Neural Dynamics in Recurrent Neural Controllers 1:37 Jannis Blüml from TU Darmstadt on HackAtari: Atari Learning Environments for Robust and Continual Reinforcement Learning 3:13 Benjamin Fuhrer from NVIDIA on Gradient Boosting Reinforcement Learning 3:54 Paul Festor from Imperial College London on Evaluating the impact of explainable RL on physician decision-making in high-fidelity simulations: insights from...
-
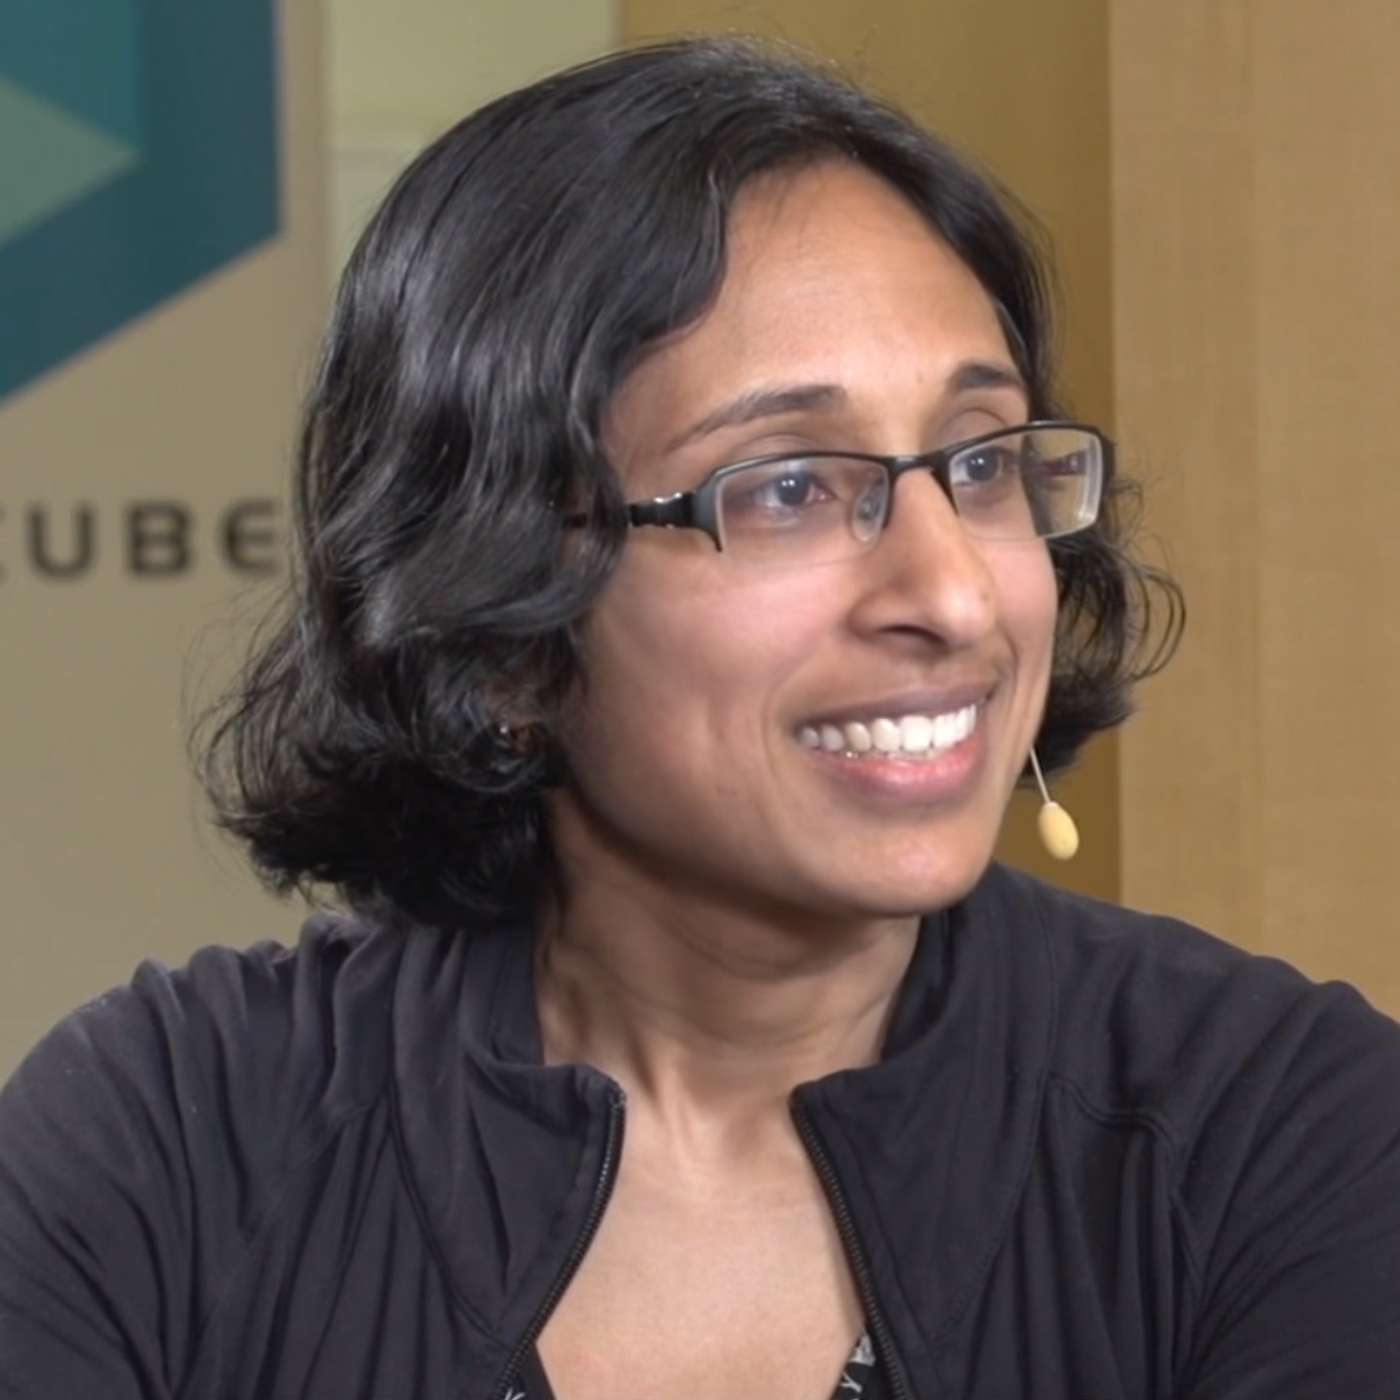 Finale Doshi-Velez on RL for Healthcare @ RCL 2024 02.09.2024 7mFinale Doshi-Velez is a Professor at the Harvard Paulson School of Engineering and Applied Sciences. This off-the-cuff interview was recorded at UMass Amherst during the workshop day of RL Conference on August 9th 2024. Host notes: I've been a fan of some of Prof Doshi-Velez' past work on clinical RL and hoped to feature her for some time now, so I jumped at the chance to get a few minutes of her thoughts -- even though you can tell I was not prepared and a bit flustered tbh. Thanks to Prof Doshi-Velez for taking a moment for this, and I hope to cross paths in future for a more in depth interv...
Similar podcasts


Popular in
The podcast also appears in the podcast charts of these countries.

