
Rapid Synthesis: My KM Pipeline, keeps me mobile and learning!
Benjamin Alloul 🗪 🅽🅾🆃🅴🅱🅾🅾🅺🅻🅼
0
This podcast series serves as a personal, on-the-go learning notebook where the host shares syntheses and explorations of artificial intelligence topics and other subjects. Episodes are produced using Google NotebookLM, a tool available to anyone. The podcast is designed to keep the host mobile and learning.
Episodes
-
 Workday Buys a Compiler 18.11.2026 35mWorkday says it will apply Honeydew's definitions directly to live Workday data, with no extracts, so agents act on today's ledger rather than yesterday's copy. This episode tests that claim. It separates what Workday is actually buying from what the announcement assumes, walks through the architecture that would have to exist, and checks Workday's record with earlier data and analytics acquisitions. The strategic argument holds: an AI model should not improvise the calculation behind a payroll number. The technical argument is narrower than the release suggests, because the live-data route al...
-
 Define Once, Compile Everywhere. Compiled, Not Guessed. 18.11.2026 37mA dashboard, a chat assistant, and an AI agent each answer "what is our headcount?" with a different number, and none of them is obviously wrong. That is the problem a semantic layer exists to solve. This episode is an independent teardown of Honeydew, the semantic layer Workday announced it intends to acquire on 18 November 2026. It covers where the business definitions physically live, what the compiler actually guarantees and what it does not, how access control travels from a user through to the warehouse, what the product costs at list price, and which buyer should walk away. The verdict...
-
 Unlimited OCR, Limited Reach 14.10.2026 1h 3mThe most-hyped open OCR model of 2026 is not the best one. Baidu's Unlimited-OCR made a splash by reading an entire multi-page PDF in a single pass. This episode unpacks what that one-shot trick costs, and who should actually use it.We explain the constant-memory attention design that keeps throughput flat across dozens of pages, then look at the catch. To fit a whole document into one pass, the model drops to a downscaled Base mode of about 256 visual tokens per page, and fine footnotes, dense tables and small type start to slip. We walk the scoreboard on OmniDocBench and olmOCR-Bench, where...
-
 The Rulebook AI Can't Compile 02.10.2026 49mMore than 80 percent of the technicians who service Western commercial aircraft are non-native English speakers, and that single number is why aviation built ASD-STE100: a controlled language of 53 writing rules and about 875 to 900 approved words, run on one axiom — one word, one part of speech, one meaning. Issue 9, published in January 2025, turned it into an international standard.This episode asks what happens when engineers point that 1986 rulebook at language models, and the answer is deflationary. It is genuinely useful as a prompt heuristic that strips filler and hedging, and as a way...
-
 Skip the Generation - Logit-Readout Architectures and OpenJEV 20.09.2026 42mExplores a shift in AI architecture toward logit-readout paradigms, often referred to as "System One" decision models, which prioritize speed and structure over conversational text generation. By analyzing the Typesafe Jev hosted baseline alongside several open-source implementations like OpenJEV and mini-JEV, the sources demonstrate how reading raw token probabilities in a single forward pass can reduce latency by 3x to 7x compared to traditional grammar-constrained generation. While these methods effectively eliminate JSON syntax errors and provide high accuracy for categorical routing, the...
-
 Dify Solo Self-Hosting 20.09.2026 51mDify Community Edition requires a shift in perspective, as the platform operates as a complex enterprise-grade microservices architecture rather than a simple developer tool. While official guides suggest lower requirements, empirical data confirms a stable deployment needs at least 8 GiB of RAM and 4 vCPUs to handle its sixteen interconnected containers and resource-intensive background tasks. Successful management for a solo operator involves using Docker Compose on a native Linux filesystem to avoid the performance and permission issues typical of Windows environments. Security is a paramou...
-
 Kestra 2.0 Self-Hosting Strategy and Architecture 20.09.2026 45mEvaluates the optimal self-hosting strategies for Kestra 2.0, specifically recommending a Docker Compose standalone deployment backed by PostgreSQL for individual operators. It warns against using the unstable embedded H2 database for anything beyond brief testing and rejects split-component architectures due to their excessive memory demands. The analysis details critical technical requirements, such as mounting the Docker socket for containerized task execution and aligning host paths to ensure seamless script performance. Additionally, the guide identifies Linux as the premier host environm...
-
 CIMD and DCR: Decentralized Architectures for OAuth Registration 19.09.2026 46mOutline the transition from Dynamic Client Registration (DCR) to OAuth Client ID Metadata Documents (CIMD) within decentralized AI architectures like the Model Context Protocol (MCP). While DCR traditionally allows applications to register with a server at runtime, it creates significant operational burdens including database bloat and security vulnerabilities like phishing. In contrast, CIMD allows a client to use a stable HTTPS URL as its identifier, shifting the responsibility of hosting metadata to the client and enabling servers to stay stateless. This architectural shift enhances securit...
-
 AI Agents in Physical Fabrication 17.09.2026 43mCurrent state of artificial intelligence agents within physical fabrication and lightweight robotics from mid-2024 to mid-2026. The text highlights a major divide between shipped, deterministic software, such as code-mediated CAD engines and automated slicing pipelines, and experimental demonstrations like autonomous robot control and multi-part assembly. While tools for instant manufacturing quotes and visual print defect detection are technically mature, more complex tasks remain hindered by geometric ambiguity and physical unreliability. Consequently, the analysis emphasizes that human vali...
-
 Agent Canvas - Part 2 - The Canvas and the Rails 17.09.2026 48mEvaluates two primary architectural frameworks for creating agent-driven user interfaces in enterprise systems: MCP Apps and Google’s A2UI. MCP Apps prioritizes flexibility by allowing servers to deliver complete, sandboxed web applications, though this can obscure visibility for security audits. In contrast, A2UI uses a declarative, data-centric approach that ensures high security and visual consistency by utilizing the host's native components. The sources suggest that a hybrid model is the most effective strategy, employing A2UI for regulated, high-stakes core functions while reserving MCP...
-
 Agent Canvas - Part 1 - Who holds the brush? 17.09.2026 32mEvaluates two primary architectural frameworks for creating agent-driven user interfaces in enterprise systems: MCP Apps and Google’s A2UI. MCP Apps prioritizes flexibility by allowing servers to deliver complete, sandboxed web applications, though this can obscure visibility for security audits. In contrast, A2UI uses a declarative, data-centric approach that ensures high security and visual consistency by utilizing the host's native components. The sources suggest that a hybrid model is the most effective strategy, employing A2UI for regulated, high-stakes core functions while reserving MCP...
-
 Unsloth: Engineering Accelerated LLM Fine-Tuning on Consumer Hardware 14.09.2026 53mUnsloth is an open-source library designed to accelerate the fine-tuning of large language models while significantly decreasing VRAM requirements through specialized Triton kernels. By manually optimizing mathematical operations, the framework prevents the buildup of memory-heavy intermediate states, allowing high-performance training on consumer-grade GPUs and free cloud environments. The software has recently expanded to support complex architectures like Mixture-of-Experts (MoE) and memory-efficient reinforcement learning via its "Standby" architecture. While it offers substantial speed an...
-
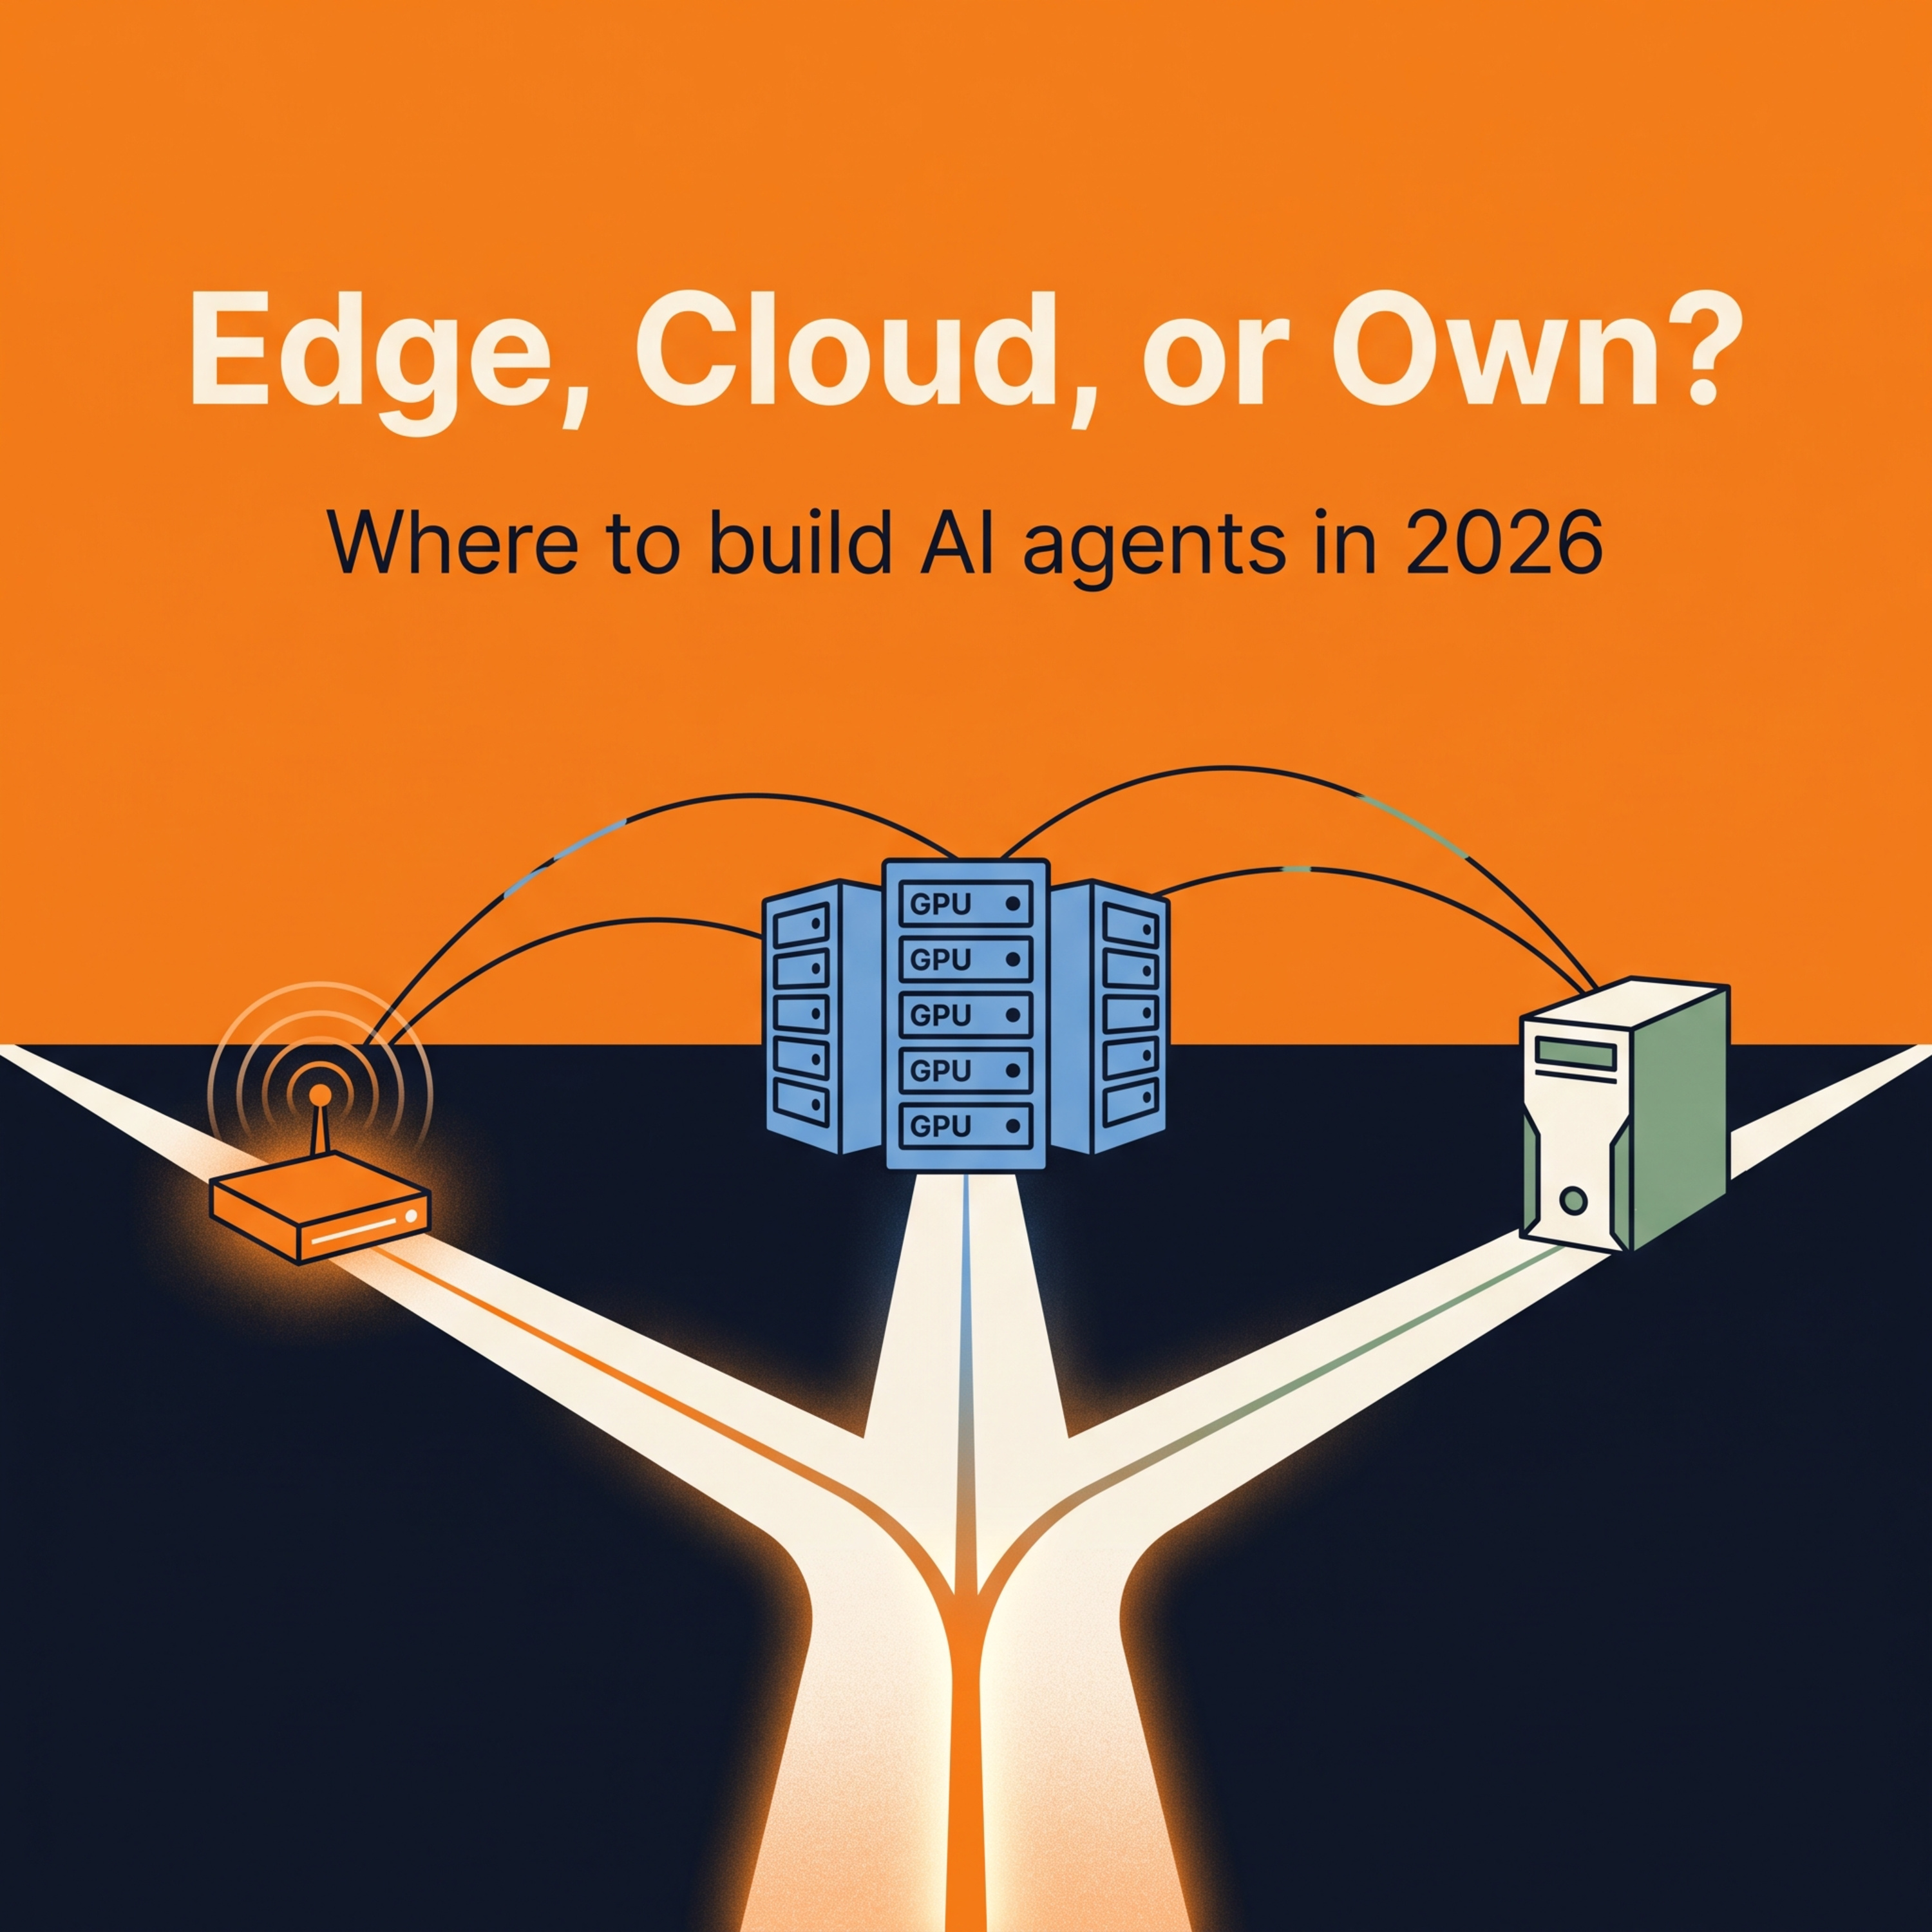 Cloudflare AI Hosting and Architectural Alternatives 14.09.2026 21mCloudflare AI platform alongside competing architectures from AWS Bedrock, developer-focused stacks like Vercel, and self-hosted GPU environments. The documentation highlights Cloudflare’s edge-native advantage, specifically its ability to maintain persistent state and execute sandboxed code with lower latency and cost than centralized hyperscalers. While AWS is noted for its superior enterprise compliance and access to proprietary models, Cloudflare is recommended for interactive agents and retrieval-augmented generation due to its integrated developer experience. The comparison also includes...
-
 Hard-Wired Silicon: AMD's Taalas Acquisition 13.09.2026 21mAMD’s acquisition of Taalas, a semiconductor startup that develops specialized silicon for Large Language Model inference. Unlike traditional GPUs that load data from external memory, the Taalas architecture physically integrates neural network weights into the chip’s hard-wired circuitry through a unique manufacturing process. This "Hard Coded Inference" approach enables massive gains in speed and energy efficiency for single-user tasks by eliminating the need to move data between processors and memory. However, this method results in model immutability, meaning any software updates require m...
-
 DeepSeek-V4.1-Flash Architecture Analysis 12.09.2026 45mDeepSeek-V4.1-Flash architecture, a high-scale language model designed to optimize the technical and economic challenges of long-context workloads. By utilizing an asymmetric Causal Encoder-Decoder structure and MXFP4 cache compression, the model significantly reduces computational waste and memory demands during data ingestion. These innovations allow for a massive 748-billion-parameter scale while maintaining efficiency through a Mixture-of-Experts backbone and advanced memory hierarchy. Furthermore, the model features native multimodal integration, unifying text and visual processing into a...
-
 The Sovereign Architect: OpenCode and the Autonomous Agent Frontier 12.09.2026 50mExamines the OpenCode and OpenWork ecosystems, which offer an open-source, model-agnostic framework for autonomous AI agents. OpenCode serves as a technical foundation for software development, utilizing a client-server architecture and specialized protocols to execute code and manage file systems.OpenWork builds upon this by providing a collaborative workspace that enables teams to automate diverse business tasks, such as data analysis and browser orchestration, across numerous AI providers. The analysis compares these tools against proprietary competitors like Claude Code and Google Antigrav...
-
 Detecting and Countering AI Misuse: September 2026 Report 11.09.2026 55mSource : https://www.anthropic.com/threat-intelligence-report-september-2026This Anthropic threat intelligence report from September 2026 details the evolving ways malicious actors attempt to exploit Claude AI models for harmful activities. The documentation highlights a shift toward autonomous cyber operations, where state-sponsored groups and criminals use AI to automate the entire cyber kill chain, from reconnaissance to data exfiltration. Notable case studies include a Russian espionage group that used AI to dynamically retool malware to evade detection and opportunistic hackers who accele...
-
 Gemini Embedding 2: Architectural Innovations and Multimodal Fusion 29.05.2026 55mArchitecture and performance of Gemini Embedding 2, a native multimodal model that maps text, images, audio, and video into a single mathematical space. Unlike traditional systems that rely on separate encoders or text transcriptions, this model uses bidirectional attention and direct sensory processing to preserve nuances like document layouts and vocal tones.It employs Matryoshka Representation Learning, allowing developers to shrink vector sizes for efficiency without losing significant accuracy.High-quality synthetic data and contrastive learning were used during training to ensure the mod...
-
 ESMFold: Language Models and High-Speed Protein Folding Structure Prediction 28.05.2026 54mExplores the development and impact of ESMFold, an advanced artificial intelligence model designed to predict protein structures with extreme speed and accuracy. By utilizing large-scale protein language models rather than traditional sequence alignments, ESMFold bypasses computational bottlenecks to generate atomic-level insights up to 60 times faster than predecessors like AlphaFold2. This technological shift has enabled massive projects such as the ESM Metagenomic Atlas, which maps the "dark matter" of the biological universe to aid in drug discovery and environmental science. While the tex...
-
 Conductor: A Technical Guide to Parallel AI Agent Orchestration 26.05.2026 44mConductor is a specialized macOS application designed to manage multiple autonomous AI coding agents simultaneously, shifting the human developer's role from a writer of code to a high-level orchestrator. By utilizing git worktrees, the platform creates isolated environments for each agent, preventing data conflicts and allowing for parallel task execution across different branches of a repository. This architectural approach enables users to delegate various features or bug fixes to separate models like Claude and Codex while maintaining a localized trust model. The system features a diff-fir...
Similar podcasts


Popular in
The podcast also appears in the podcast charts of these countries.
